Tag
#agent-benchmarks
3 articles
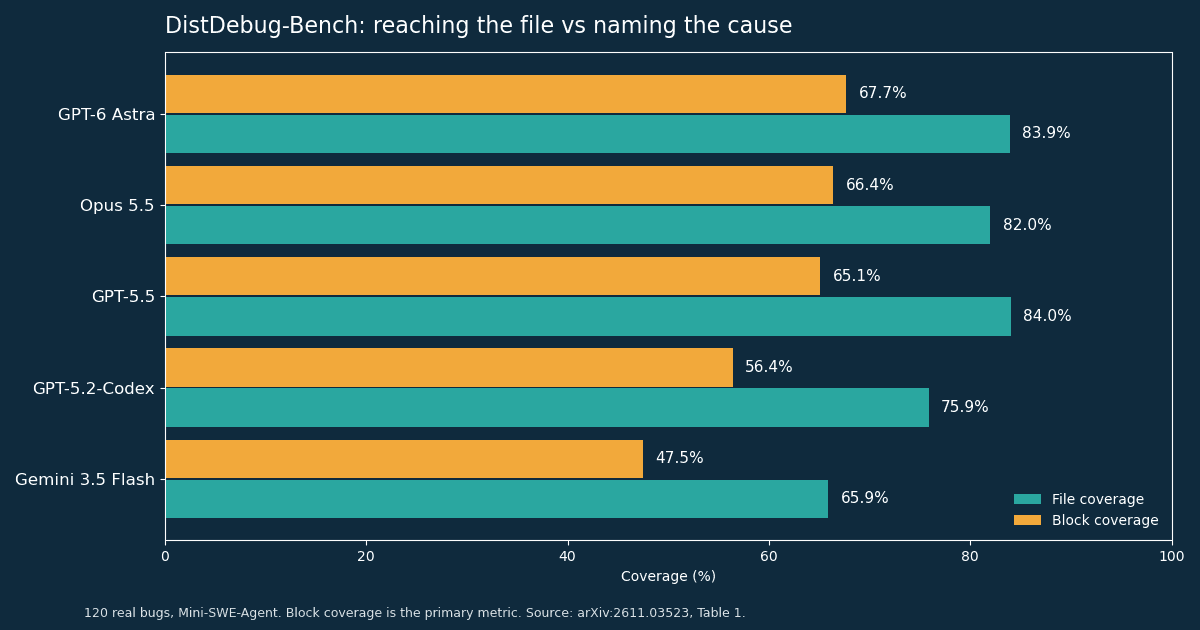
Agents Find the File and Miss the Cause, and the Gap Grows on Thin Evidence
On 120 real distributed-system bugs, the best agent finds the right file 83.9% of the time but names the causal code block only 67.7% of the time. The gap widens to a 29.8 point drop on reports that name no method and carry no stack trace.
Ibrahim Denis Fofanah·Nov 4, 2026·12 min
Switching Agent Harnesses Changed 13% of Tasks. Rerunning the Same One Changed 13% Too
Five models, three production harnesses, 447 real GitHub issues. Claude Code and mini-SWE-agent land within five points of each other, a harness swap flips as many tasks as a rerun, and cost per task differs up to 3x. The wrapper decides the bill, not the score.
Ibrahim Denis Fofanah·Oct 27, 2026·10 min
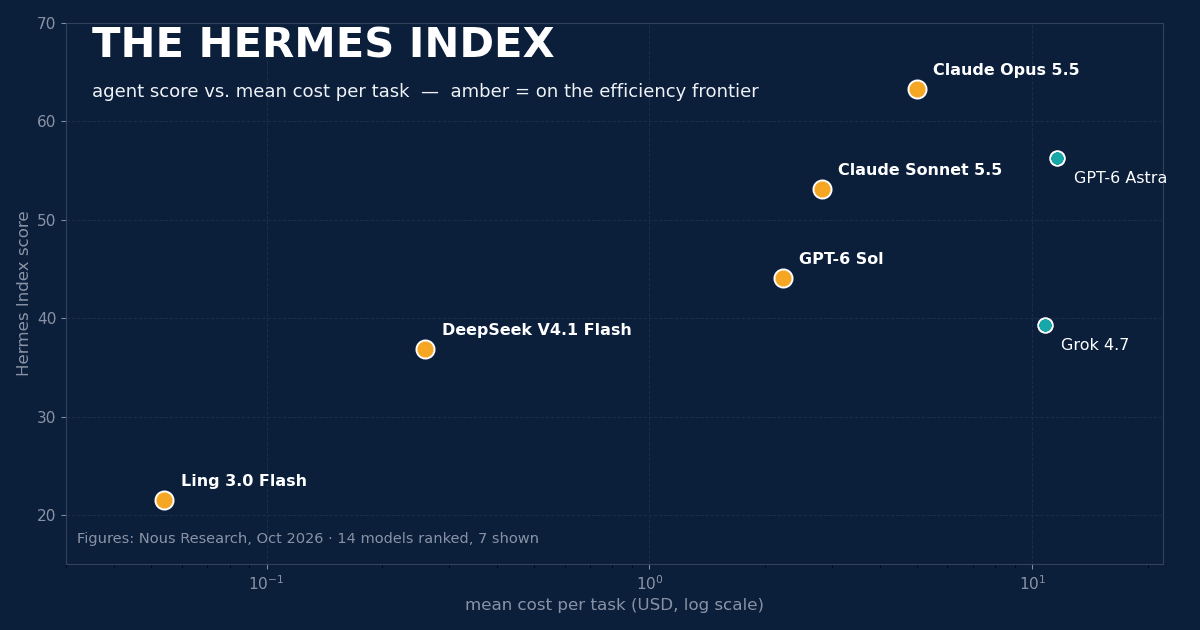
The Hermes Index Ranks Agent Models on Score and Cost. The Lab That Built It Just Raised $90M.
Nous Research's Hermes Index (Oct 6, 2026) pairs agent scores with cost per task for 14 models. Opus 5.5 leads on score at 63.31; the value story belongs to Sonnet 5.5 and DeepSeek V4.1 Flash.
Ibrahim Denis Fofanah·Oct 10, 2026·8 min