Agentic AI
 Deep DiveBuilding Agentic AI Systems · Deep Dive
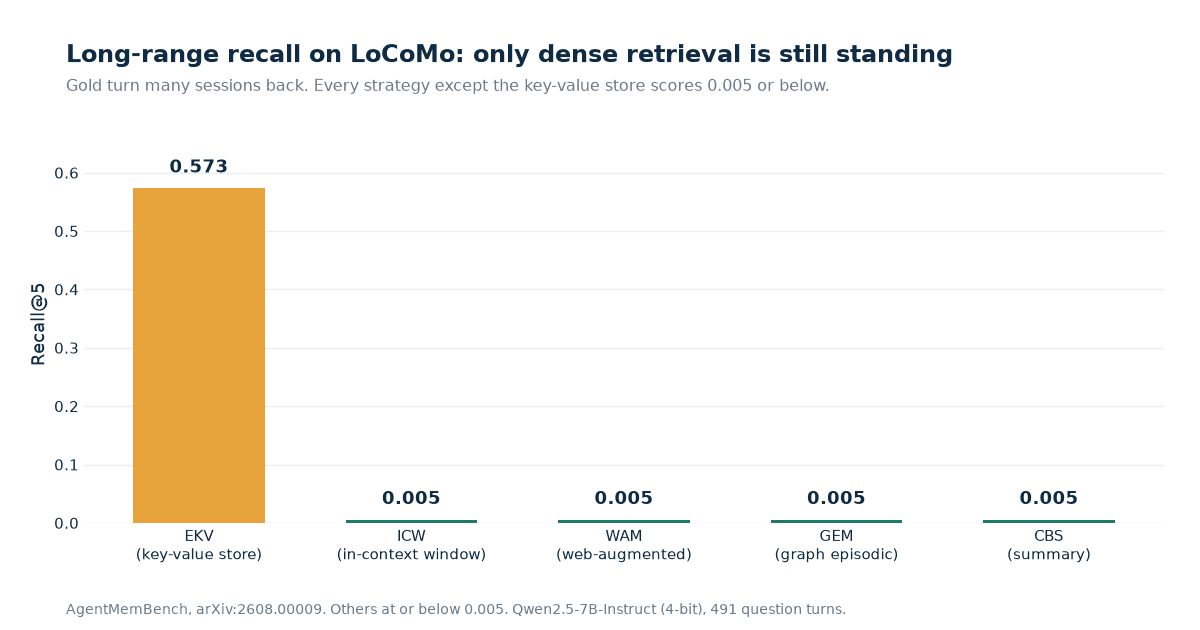
Agent Memory Is Three Systems, Not One. Five Papers Prove the Split
Five papers split agent memory into three jobs: factual recall, behavioural rules, and the cost of remembering. Dense retrieval wins long horizons, compaction beats raw transcripts until wording matters, and corrections need rules, not search.
Ibrahim Denis Fofanah·Nov 11, 2026·14 min
 Benchmark WatchAgent Evaluation · Benchmark Watch
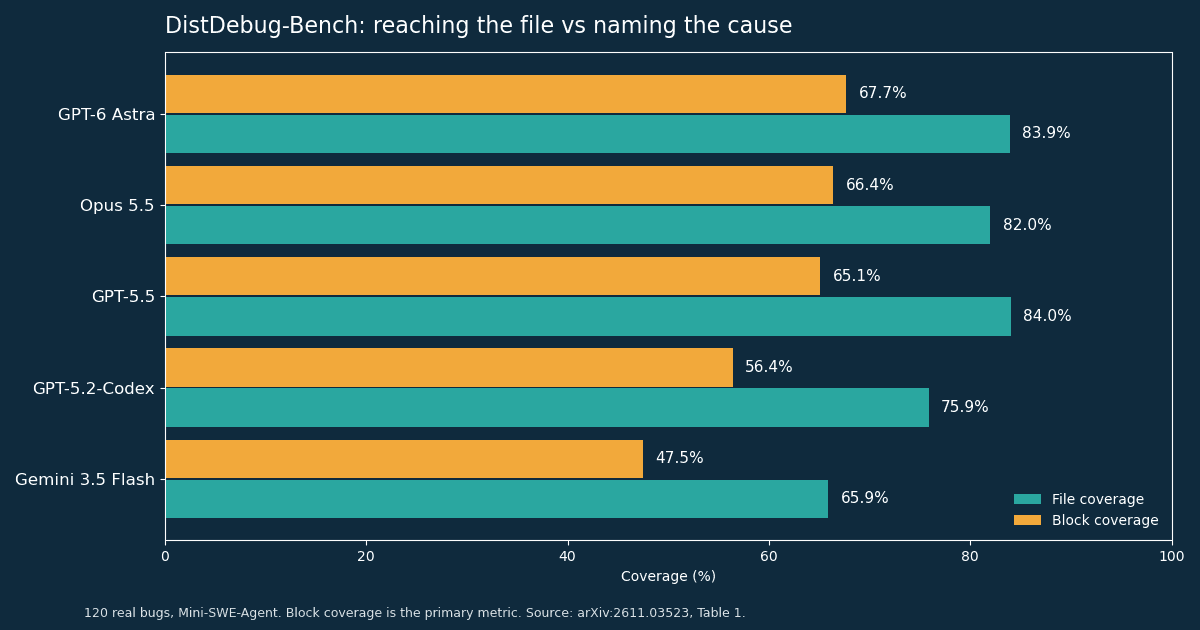
Agents Find the File and Miss the Cause, and the Gap Grows on Thin Evidence
On 120 real distributed-system bugs, the best agent finds the right file 83.9% of the time but names the causal code block only 67.7% of the time. The gap widens to a 29.8 point drop on reports that name no method and carry no stack trace.
Ibrahim Denis Fofanah·Nov 4, 2026·12 min
- arXiv BreakdownAgents & Evaluation · arXiv Breakdown
Switching Agent Harnesses Changed 13% of Tasks. Rerunning the Same One Changed 13% Too
Five models, three production harnesses, 447 real GitHub issues. Claude Code and mini-SWE-agent land within five points of each other, a harness swap flips as many tasks as a rerun, and cost per task differs up to 3x. The wrapper decides the bill, not the score.
Ibrahim Denis Fofanah·Oct 27, 2026·10 min
 arXiv BreakdownBuilding Agents That Hold Up · Agentic AI
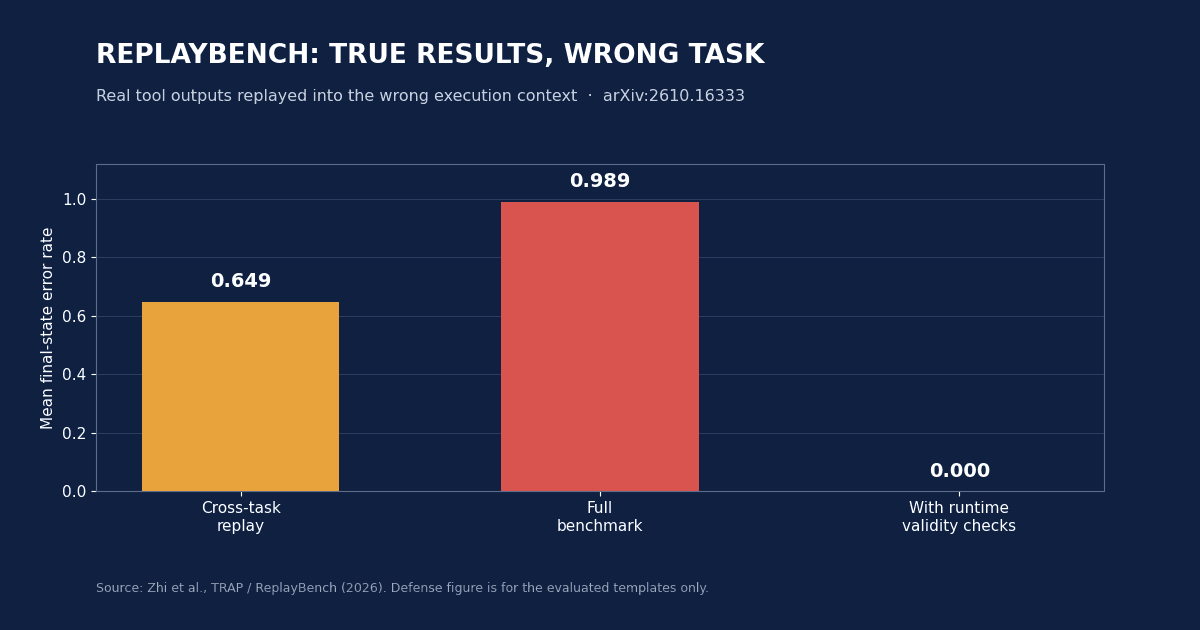
A True Tool Result Can Still Be Wrong: ReplayBench Found a 64.9% Error Rate
TRAP replayed real, unmodified tool results into the wrong task. Agents acted on them anyway: mean final-state error 0.649, and 0.989 across the full benchmark.
Ibrahim Denis Fofanah·Oct 20, 2026·11 min
 Benchmark WatchBuilding Agentic AI Systems · Benchmark Watch
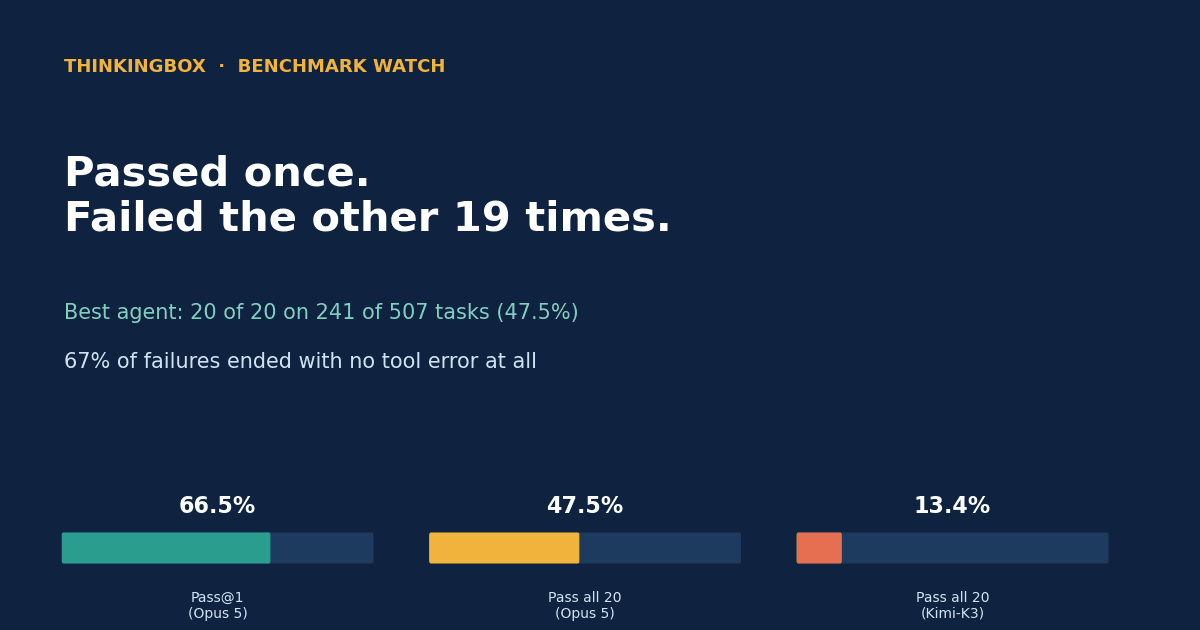
Passed Once Is Not Reliable: ThinkingBox Grades Agents on the Database, Not the Demo
ThinkingBox checks the final database state after an agent finishes, not its summary. Across 121,680 trials, 79,853 failed, and 67% of failures ended with no tool error. One good demo is not reliability.
Ibrahim Denis Fofanah·Oct 15, 2026·7 min
 New ReleaseCost Per Task Is the Real Benchmark · Agentic AI
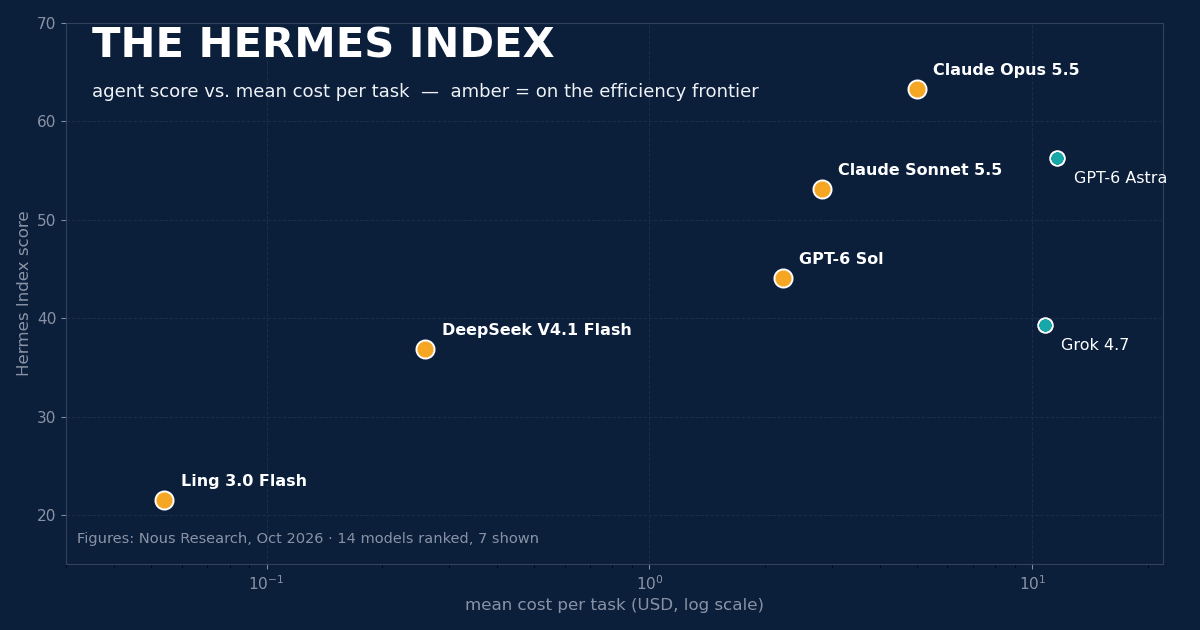
The Hermes Index Ranks Agent Models on Score and Cost. The Lab That Built It Just Raised $90M.
Nous Research's Hermes Index (Oct 6, 2026) pairs agent scores with cost per task for 14 models. Opus 5.5 leads on score at 63.31; the value story belongs to Sonnet 5.5 and DeepSeek V4.1 Flash.
Ibrahim Denis Fofanah·Oct 10, 2026·8 min
 ExplainerAgentic AI · Explainer
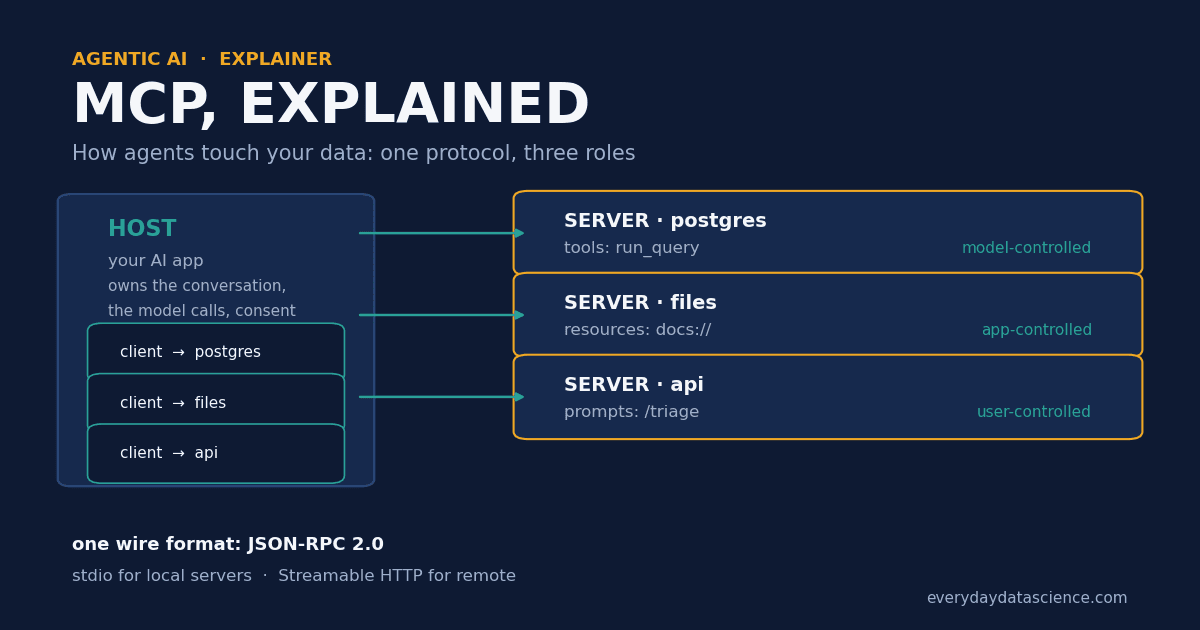
MCP, Explained for Data People: It Standardizes the Plumbing, Not the Thinking
MCP standardizes how agents connect to data and tools: three roles, three primitives, one wire format. I built a minimal server and ran it end to end; here is what the protocol guarantees, and the security fine print most tutorials skip.
Ibrahim Denis Fofanah·Oct 4, 2026·9 min
 AnalysisAI Engineering · Agentic AI
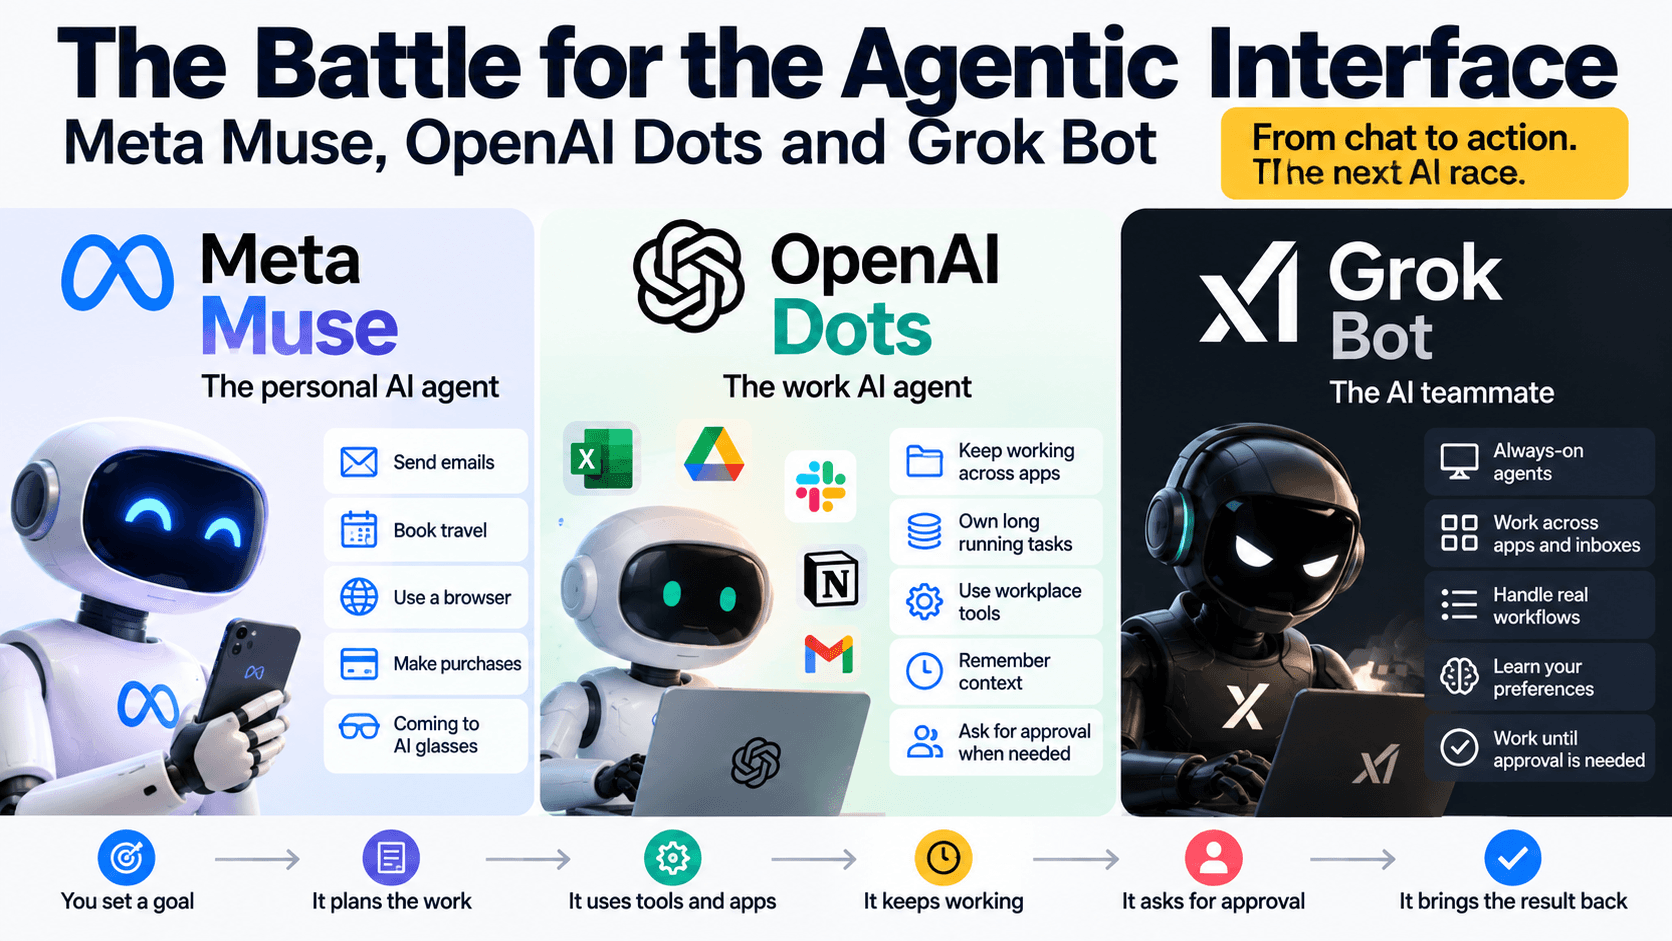
The Battle for the Agentic Interface: Meta Muse, OpenAI Dots and Grok Bot
Meta Muse, OpenAI Dots and Grok Bot point to a new AI interface: persistent agents that can use tools, maintain state and keep working after the chat ends.
Rodriquez Allen·Oct 3, 2026·9 min
 Tutorial
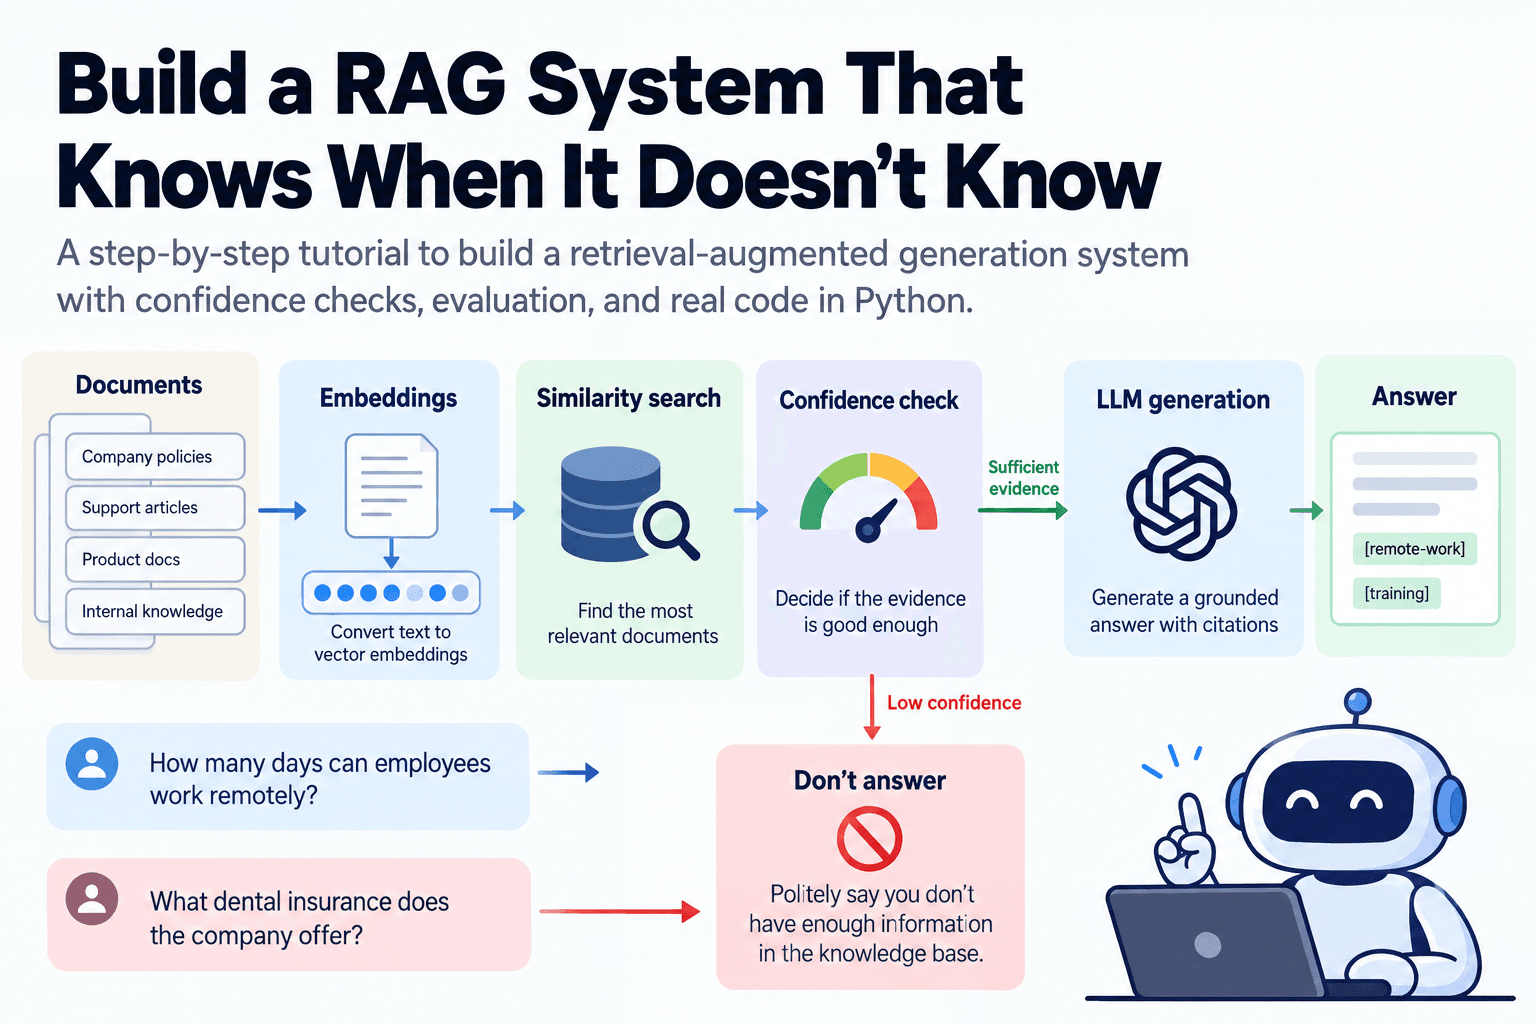
Build a RAG System That Knows When It Doesn't Know
A practical AI engineering tutorial on building a retrieval-augmented generation system with semantic search, confidence checks, grounded answers, and a simple evaluation layer.
Rodriquez Allen·Oct 2, 2026·8 min
 Research BriefThe Agent Frontier · Research Brief
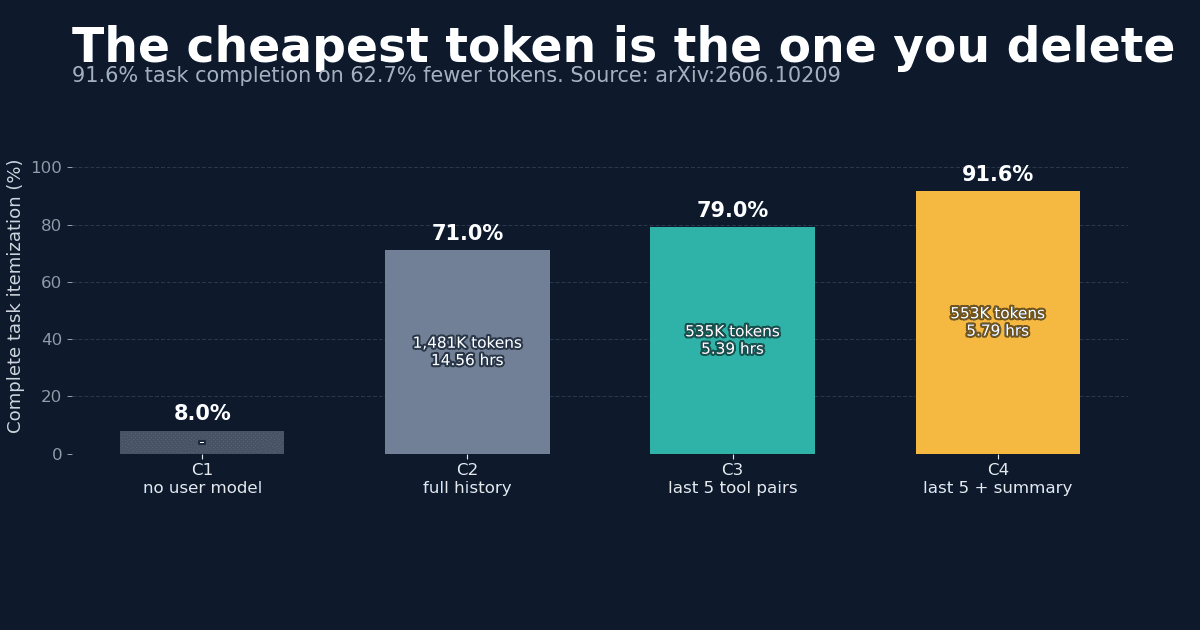
Delete 62% of your agent's context. It gets better, not worse.
Agent bills keep growing because trajectories keep growing. Three new papers show that cutting context by 40 to 63% lowers cost and, counterintuitively, raises accuracy. Here is the evidence, the caveats, and the five-minute fix you can ship today.
Ibrahim Denis Fofanah·Sep 30, 2026·7 min
 TutorialBuild It Yourself · Agentic AI
Stop Eyeballing Your Agent's Answers. A 100-Line Eval Harness Catches the Regressions You Miss.
Every agent builder hand-tests a few prompts and calls it evaluation. This tutorial builds a 100-line Python harness with a fixed case set, runs it against two versions of a mock agent, and catches a regression that eyeballing would have missed.
Ibrahim Denis Fofanah·Sep 27, 2026·7 min
- AnalysisResearch Analysis · Agentic Work
3.1 Agent Workdays per Human Day Is Not 3.1× Productivity
OpenAI reports 3.1 agent-workdays of runtime for every human workday in its research organization. The number shows a major workflow shift, but runtime, useful output, and scientific progress are not the same metric.
Ibrahim Denis Fofanah·Sep 25, 2026·7 min