Agentic AI
17 articles
0 followers
2 results Clear
- arXiv BreakdownAgents & Evaluation · arXiv Breakdown
Switching Agent Harnesses Changed 13% of Tasks. Rerunning the Same One Changed 13% Too
Five models, three production harnesses, 447 real GitHub issues. Claude Code and mini-SWE-agent land within five points of each other, a harness swap flips as many tasks as a rerun, and cost per task differs up to 3x. The wrapper decides the bill, not the score.
Ibrahim Denis Fofanah·Oct 27, 2026·10 min
 arXiv BreakdownBuilding Agents That Hold Up · Agentic AI
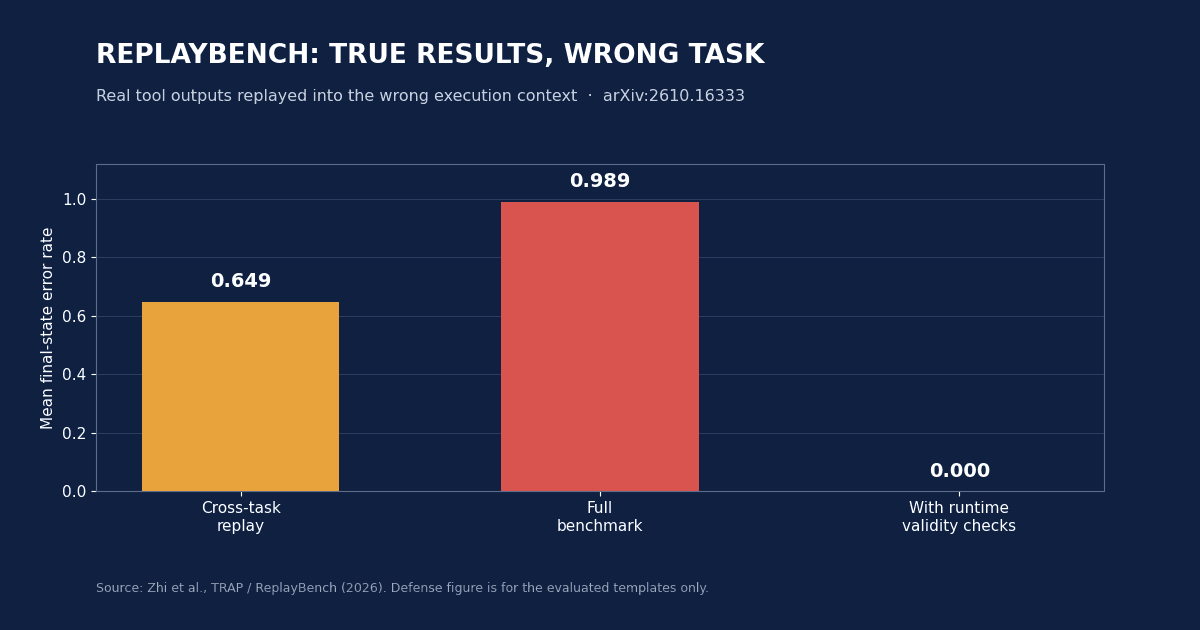
A True Tool Result Can Still Be Wrong: ReplayBench Found a 64.9% Error Rate
TRAP replayed real, unmodified tool results into the wrong task. Agents acted on them anyway: mean final-state error 0.649, and 0.989 across the full benchmark.
Ibrahim Denis Fofanah·Oct 20, 2026·11 min