Tag
#benchmarks
4 articles
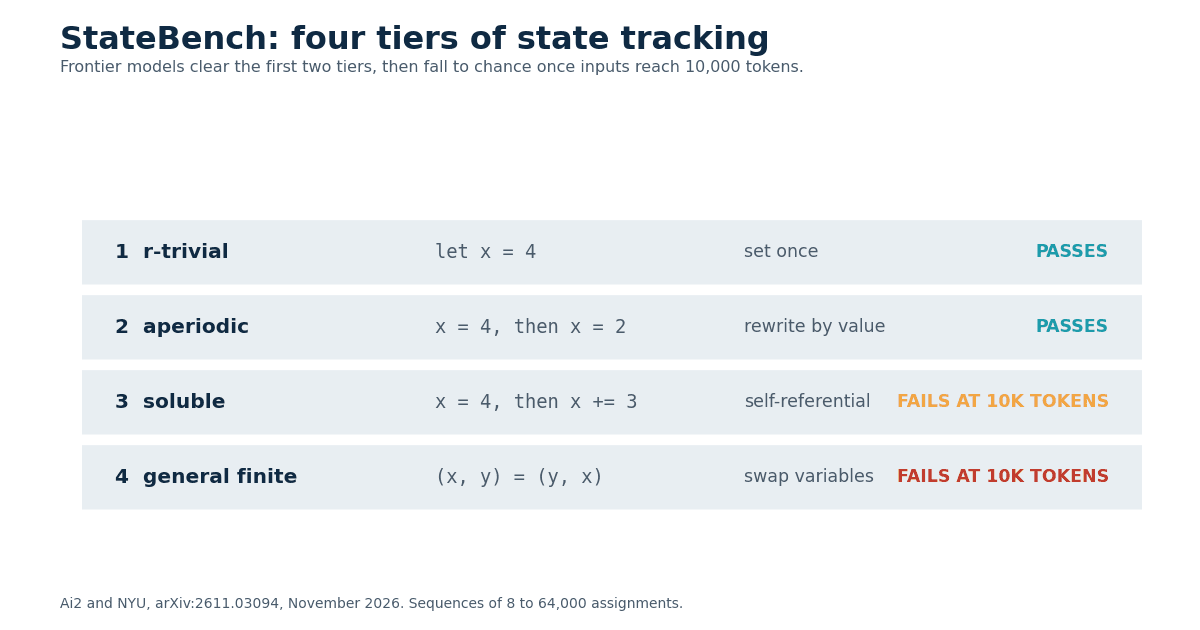
The Best Models Track State Well. At 10,000 Tokens, They Fall to Chance
StateBench tests state tracking across 8 to 64,000 assignments. Frontier models handle the easy tiers, then fall to chance on soluble and general finite tracking once inputs reach 10,000 tokens.
Ibrahim Denis Fofanah·Nov 8, 2026·12 min
Frontier Models Can Spot a Broken Experiment. They Still Pick It One Time in Five
Tampered ML gave 22 frontier models 1,858 pairs of near-identical experiment proposals, one sound and one with a single planted flaw. The best model was right in both orders 77.9% of the time. Order swaps, added detail, and conventional practice flipped the rest.
Ibrahim Denis Fofanah·Oct 30, 2026·11 min
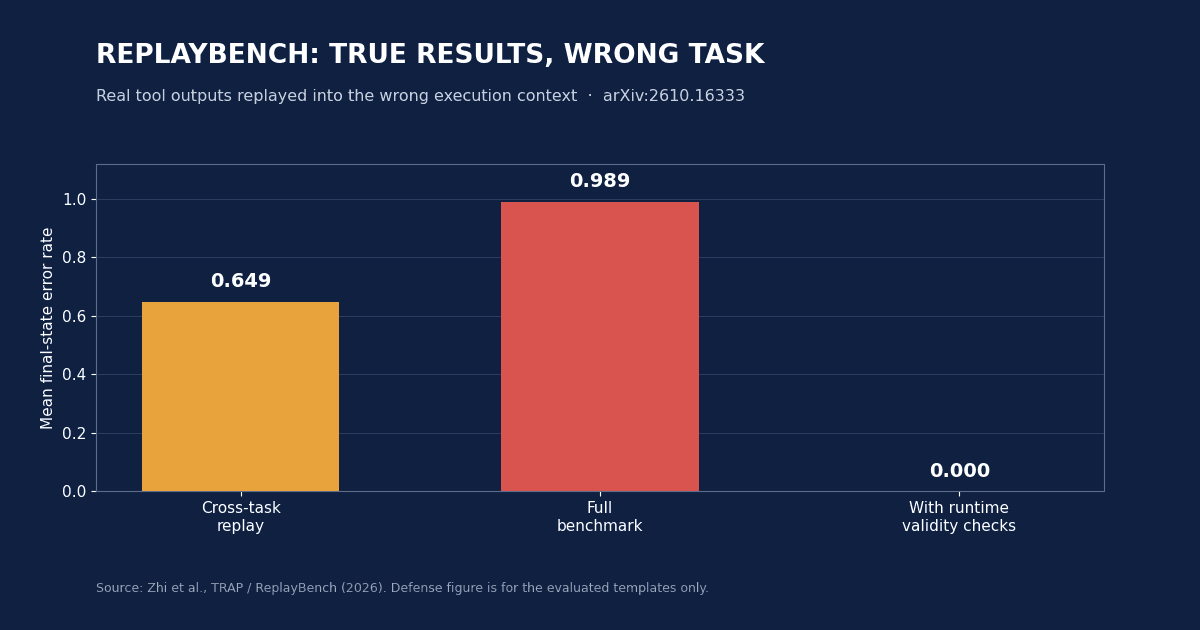
A True Tool Result Can Still Be Wrong: ReplayBench Found a 64.9% Error Rate
TRAP replayed real, unmodified tool results into the wrong task. Agents acted on them anyway: mean final-state error 0.649, and 0.989 across the full benchmark.
Ibrahim Denis Fofanah·Oct 20, 2026·11 min
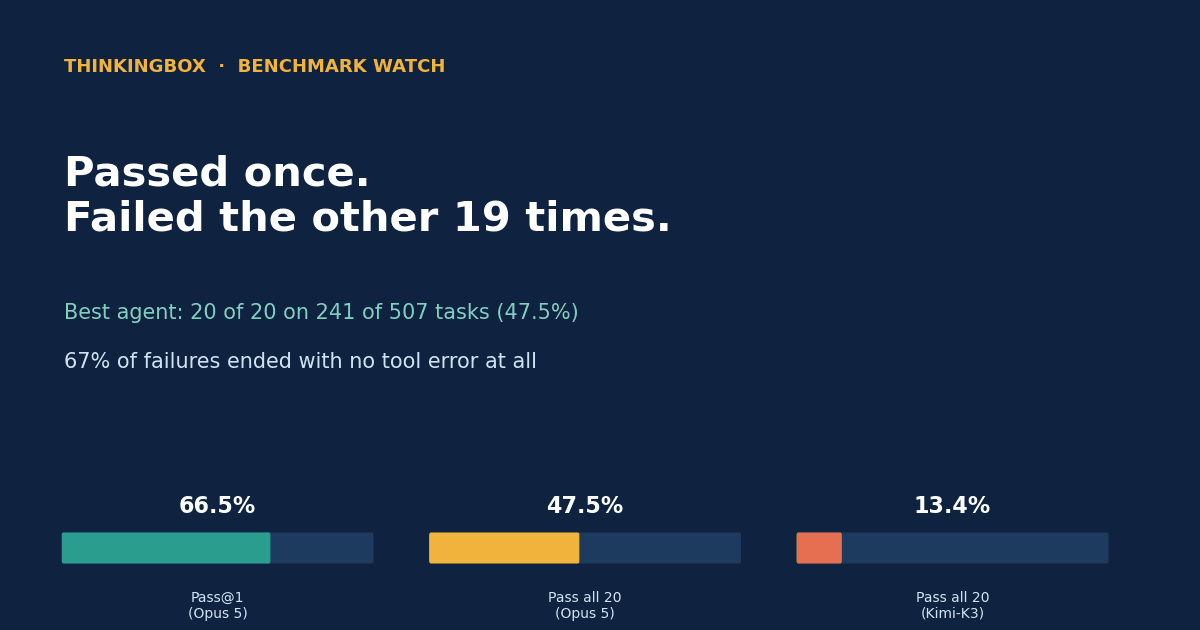
Passed Once Is Not Reliable: ThinkingBox Grades Agents on the Database, Not the Demo
ThinkingBox checks the final database state after an agent finishes, not its summary. Across 121,680 trials, 79,853 failed, and 67% of failures ended with no tool error. One good demo is not reliability.
Ibrahim Denis Fofanah·Oct 15, 2026·7 min