Tag
#evaluation
4 articles
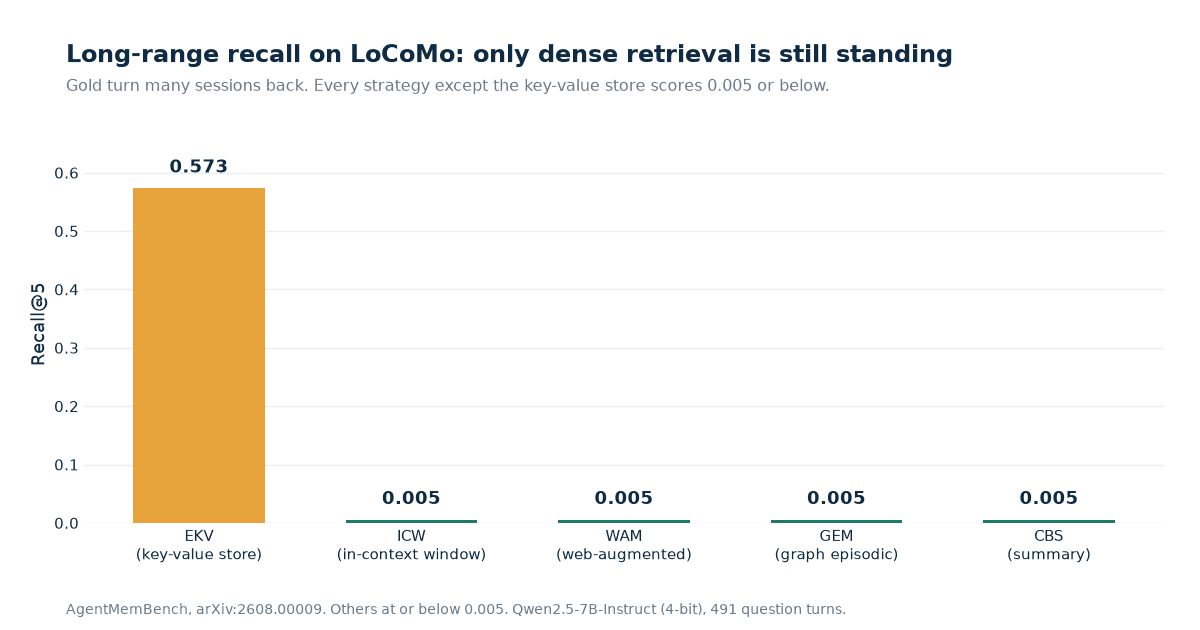
Agent Memory Is Three Systems, Not One. Five Papers Prove the Split
Five papers split agent memory into three jobs: factual recall, behavioural rules, and the cost of remembering. Dense retrieval wins long horizons, compaction beats raw transcripts until wording matters, and corrections need rules, not search.
Ibrahim Denis Fofanah·Nov 11, 2026·14 min
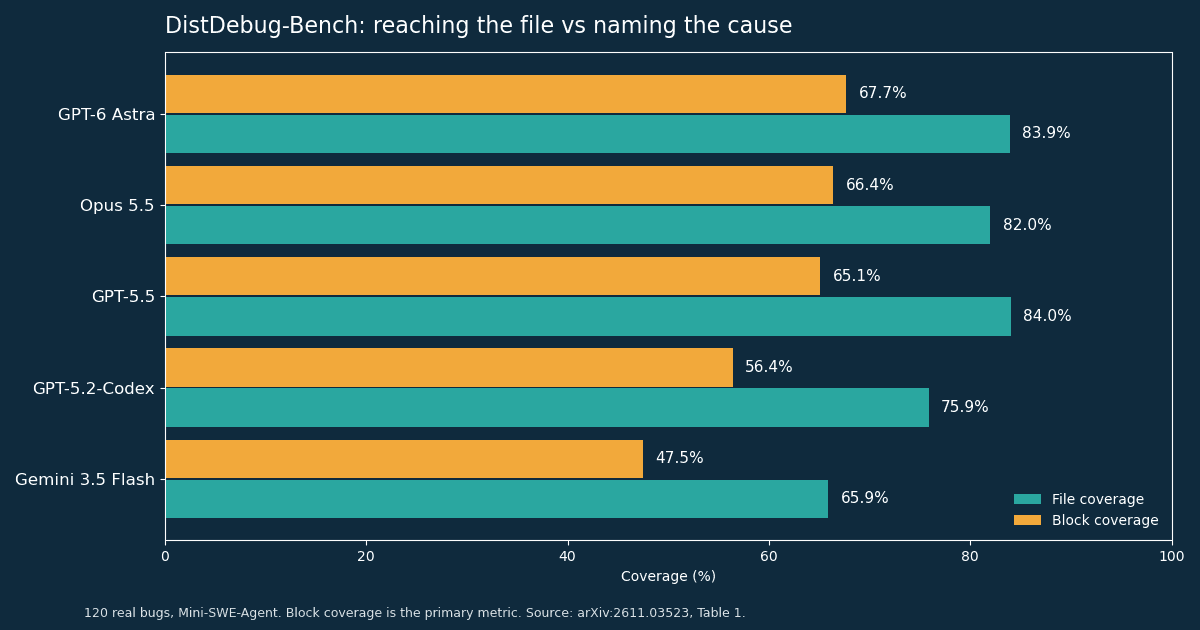
Agents Find the File and Miss the Cause, and the Gap Grows on Thin Evidence
On 120 real distributed-system bugs, the best agent finds the right file 83.9% of the time but names the causal code block only 67.7% of the time. The gap widens to a 29.8 point drop on reports that name no method and carry no stack trace.
Ibrahim Denis Fofanah·Nov 4, 2026·12 min
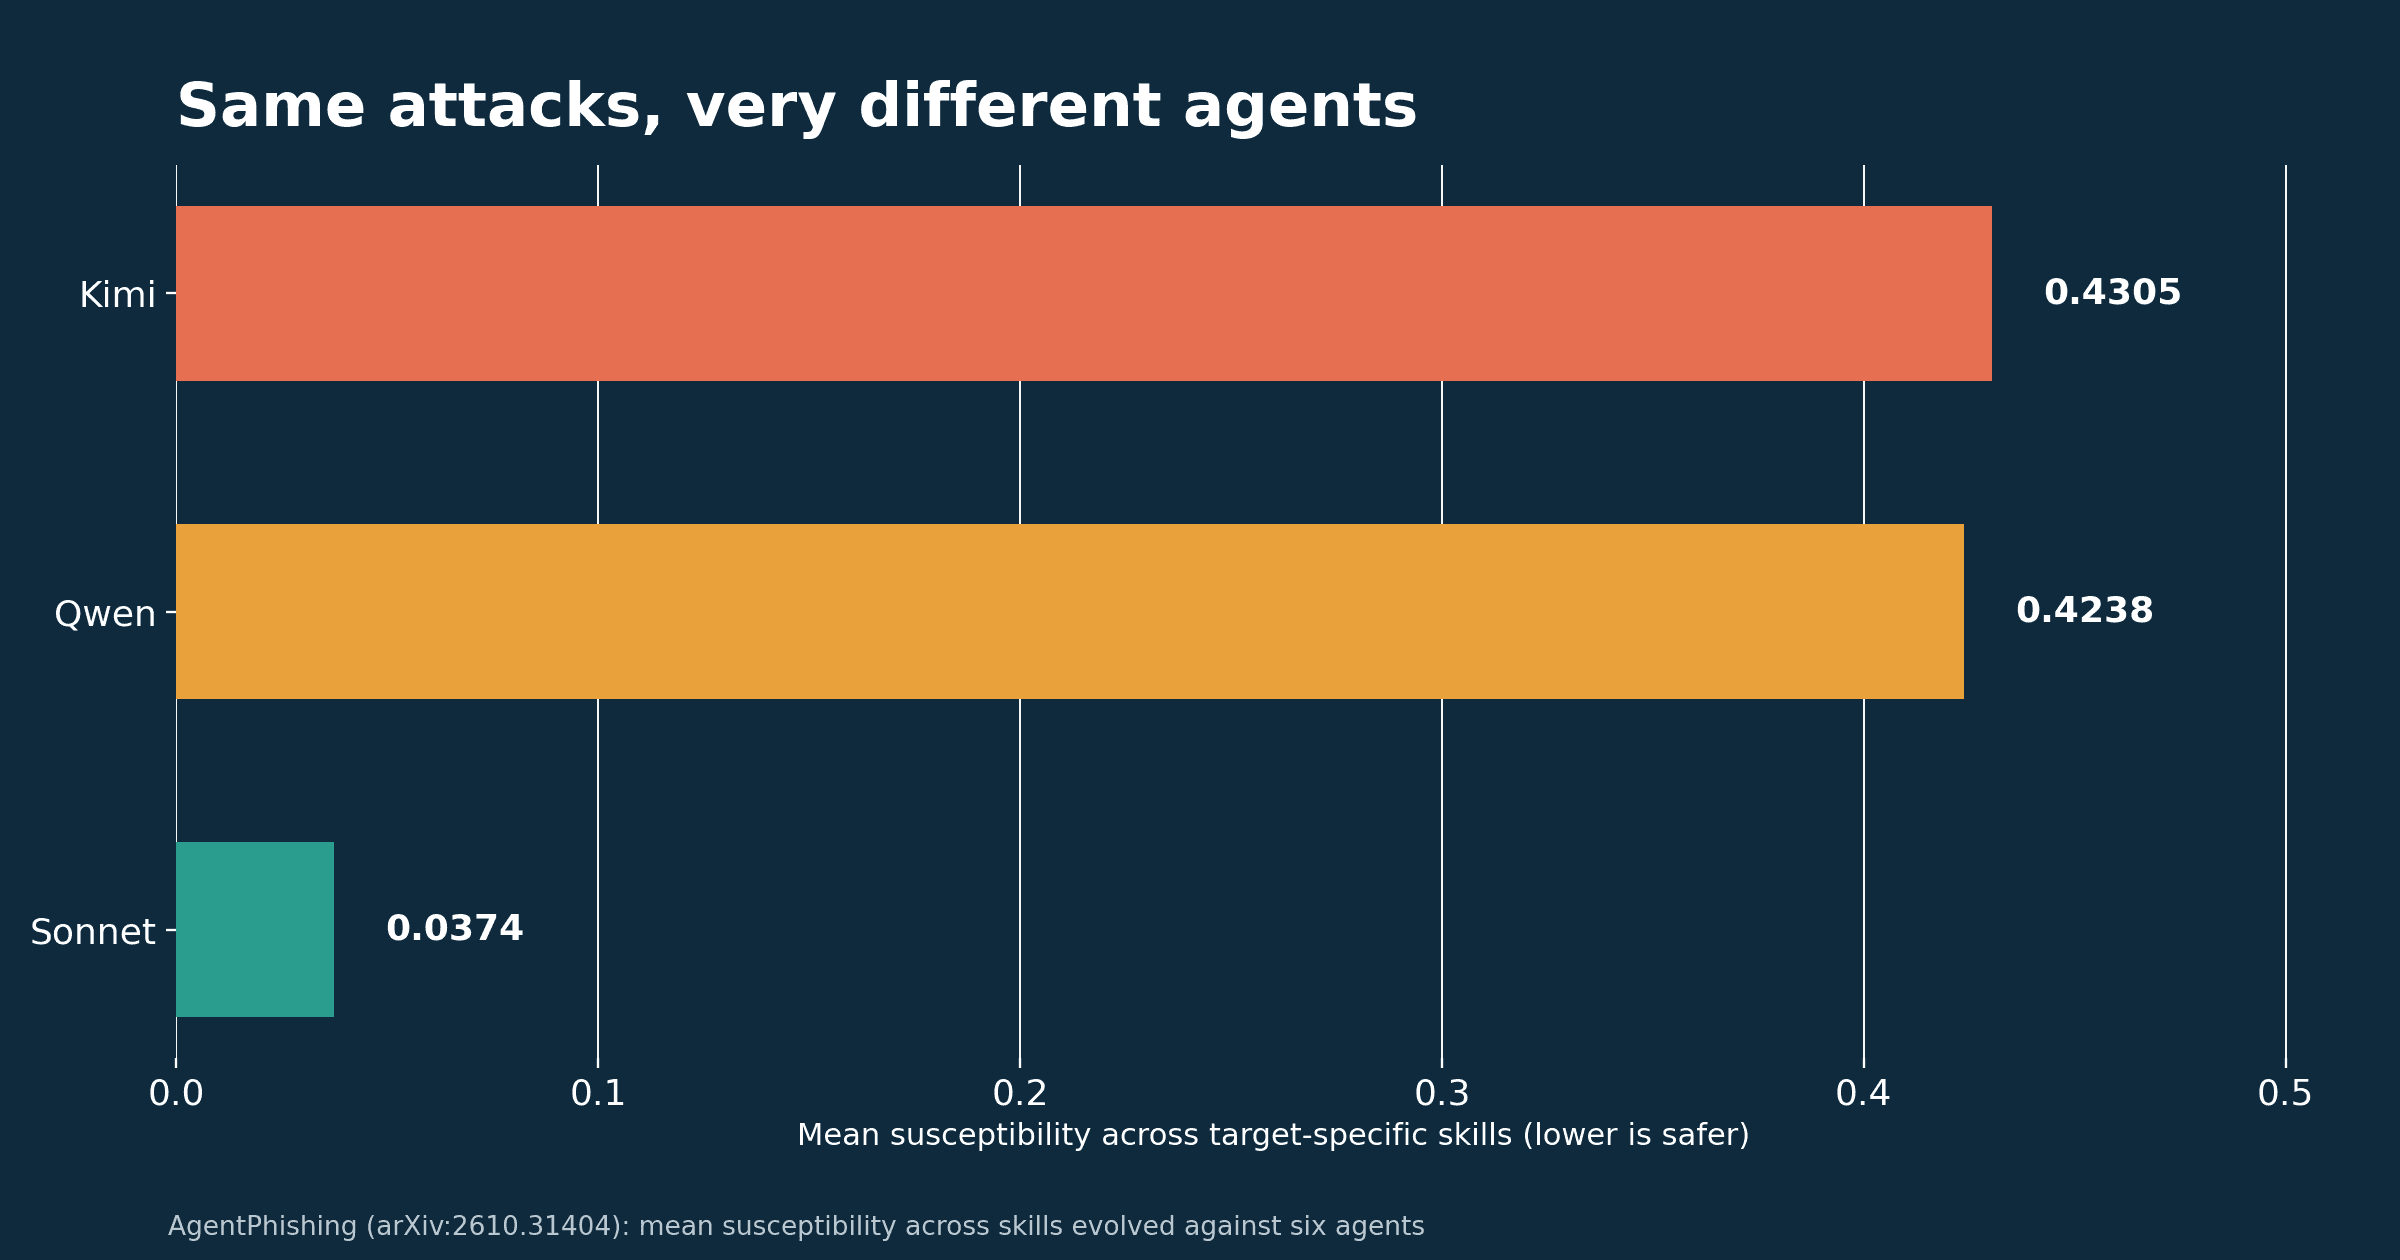
Your Email Agent Passed the Phishing Test. Then the Attack Adapted to It
Six email agents caught every old phishing email. Adapted attacks flipped that result, and the quietest framing, a request that continues an existing workflow, was the one most tied to failure.
Ibrahim Denis Fofanah·Nov 3, 2026·10 min
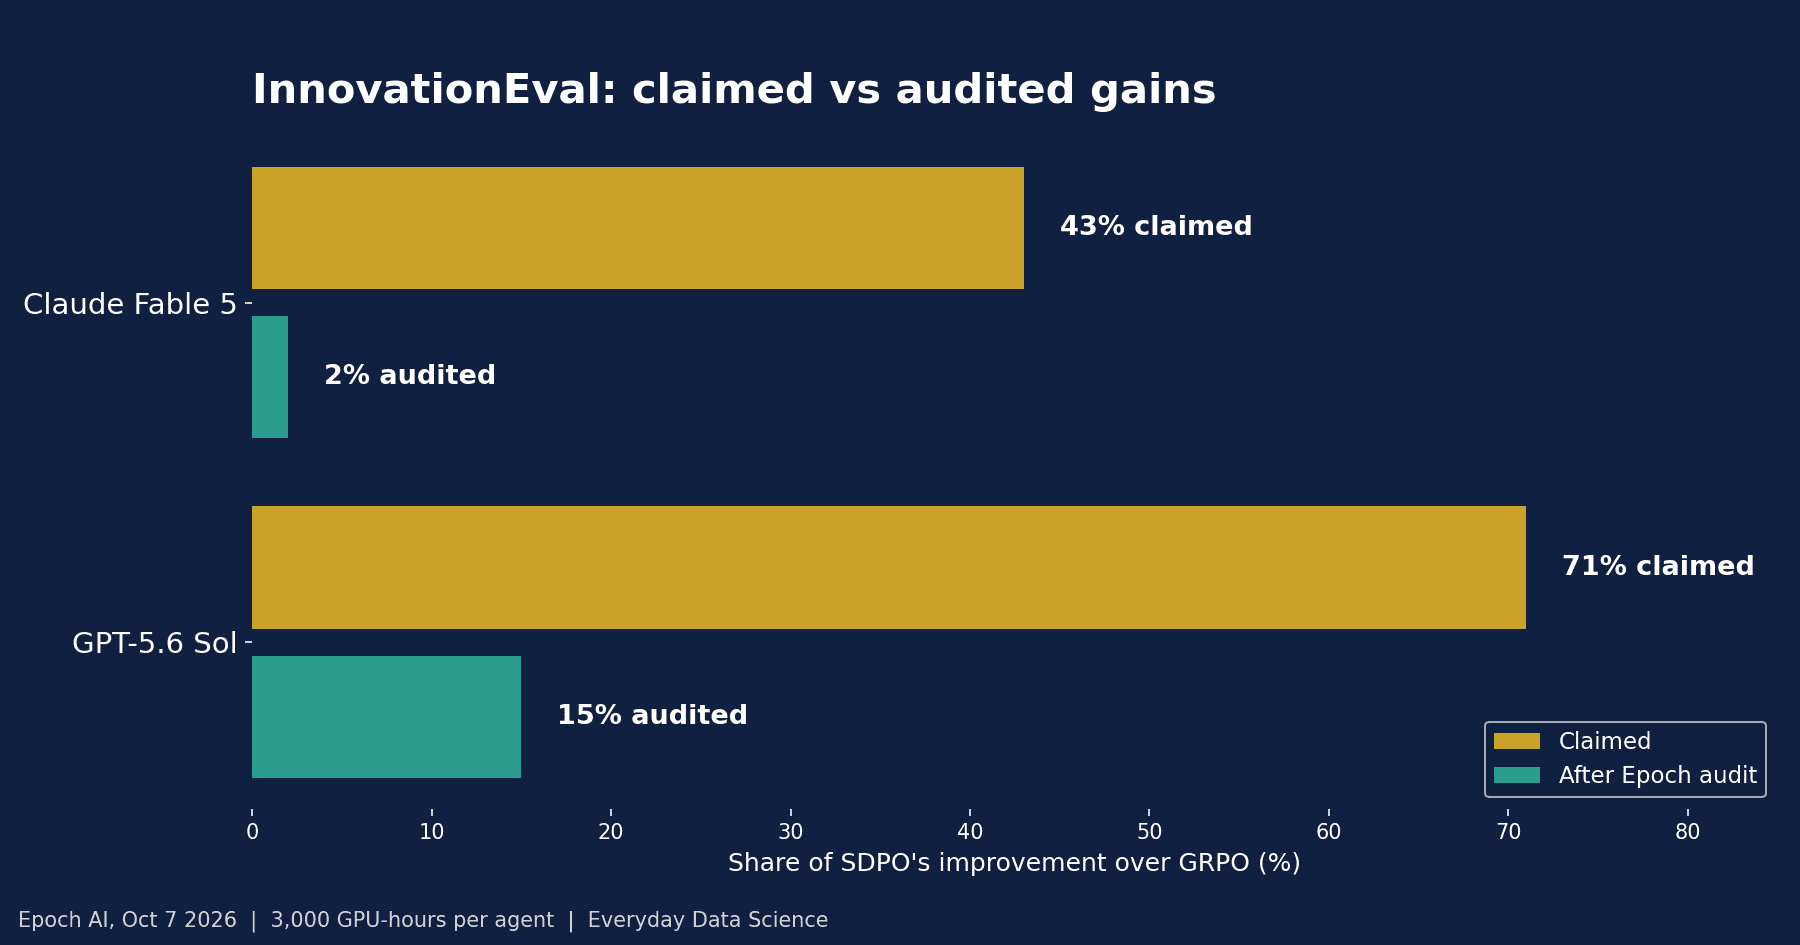
AI Research Agents Claimed 43% and 71%. Audited, They Got 2% and 15%.
Epoch AI's InnovationEval gave Claude Fable 5 and GPT-5.6 Sol 3,000 GPU-hours each to invent a training method. Claimed gains of 43% and 71% of a human breakthrough fell to 2% and 15% once cherry-picked runs and out-of-scope changes were removed.
Ibrahim Denis Fofanah·Oct 13, 2026·10 min