Ibrahim Denis Fofanah
Data Scientist & AI Researcher
Data scientist and AI researcher at Pace University. I coined Artificial Frictional Unemployment, and built the first machine learning model for crop yield prediction in Sierra Leone. Author of Understanding Agentic AI. I write about agentic systems and applied ML, with a bias toward what actually works, and who gets left out when it doesn't.
Your Query Is Slow. EXPLAIN Told You Why: Five Plan Checks That Catch It Before Users Do
Five EXPLAIN QUERY PLAN checks on 100,000 SQLite rows: SCAN versus SEARCH, a covering index, a join plan, a temp sort, and a LIKE trap where the index did not rescue the query at all.
Ibrahim Denis Fofanah·Oct 31, 2026·7 min
Frontier Models Can Spot a Broken Experiment. They Still Pick It One Time in Five
Tampered ML gave 22 frontier models 1,858 pairs of near-identical experiment proposals, one sound and one with a single planted flaw. The best model was right in both orders 77.9% of the time. Order swaps, added detail, and conventional practice flipped the rest.
Ibrahim Denis Fofanah·Oct 30, 2026·11 min
79% Accurate, Give or Take 8 Points: What a Bootstrap Interval Says About Your Test Score
One logistic model scored on test sets of 100, 400, and 1,600 rows. The 95% bootstrap interval shrank from 17 points wide to 4 as the test set grew, and 20 fresh test sets of 400 rows landed anywhere from 73.8% to 82.3%. Report the interval with the score.
Ibrahim Denis Fofanah·Oct 29, 2026·8 min
100% Refusal, 0.4% Good: Safety Alignment in Hausa Is Measuring the Wrong Thing
The base model refuses 100% of harmful Hausa prompts, yet 96.2% of its refusals are low quality. SFT teaches fluency, DPO teaches precision, and no configuration delivers both.
Ibrahim Denis Fofanah·Oct 28, 2026·13 min
Switching Agent Harnesses Changed 13% of Tasks. Rerunning the Same One Changed 13% Too
Five models, three production harnesses, 447 real GitHub issues. Claude Code and mini-SWE-agent land within five points of each other, a harness swap flips as many tasks as a rerun, and cost per task differs up to 3x. The wrapper decides the bill, not the score.
Ibrahim Denis Fofanah·Oct 27, 2026·10 min
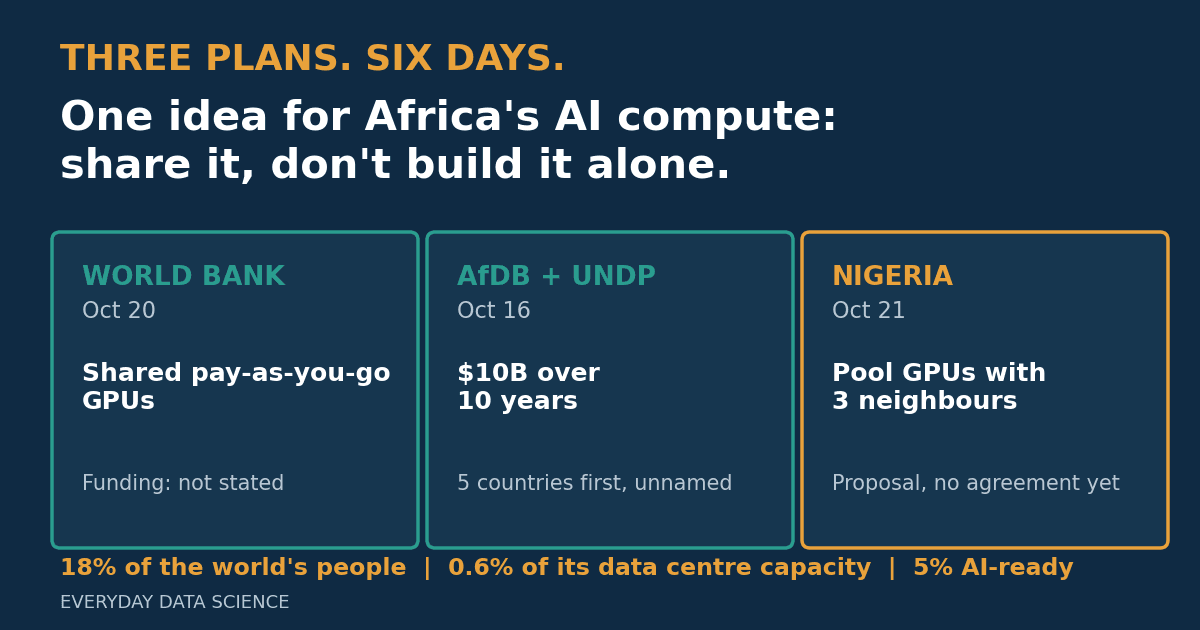
Three Plans to Share Africa's AI Computing Power Landed in Six Days. The Hard Numbers Are Still Missing.
In six days, three separate proposals told African governments the same thing: do not build your own AI data centre, share the computing instead. One has $10 billion attached. One has no funding figure at all. One is a proposal between four countries.
Ibrahim Denis Fofanah·Oct 26, 2026·14 min
Five Aggregation Traps That Rewrite Your Totals. I Measured Each One on Twelve Rows.
Five aggregation traps measured on one 12-row sales table in SQLite 3.45.1: integer division, averages of averages, COUNT(*) vs COUNT(column), the NULL group, and WHERE vs HAVING.
Ibrahim Denis Fofanah·Oct 25, 2026·10 min
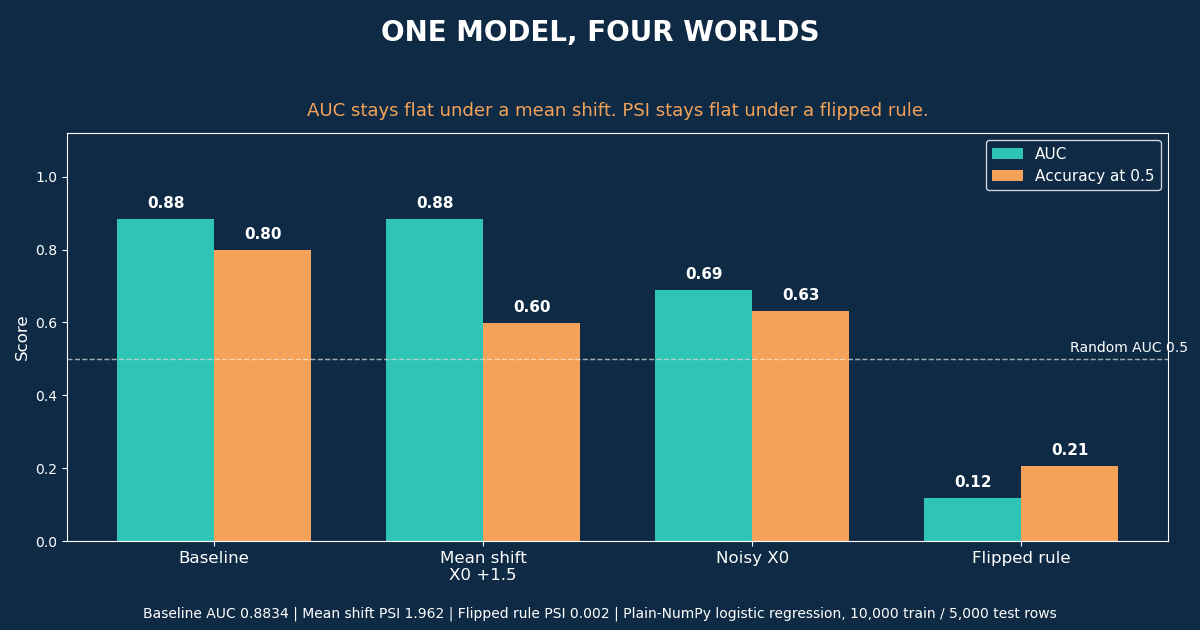
Drift Is Three Different Failures, and One Metric Cannot See Them All
One logistic model, four test scenarios: a mean shift that broke accuracy but not AUC, added noise that hurt both, and a flipped rule that PSI could not see at all. The table, the code, and the monitoring checklist.
Ibrahim Denis Fofanah·Oct 24, 2026·9 min
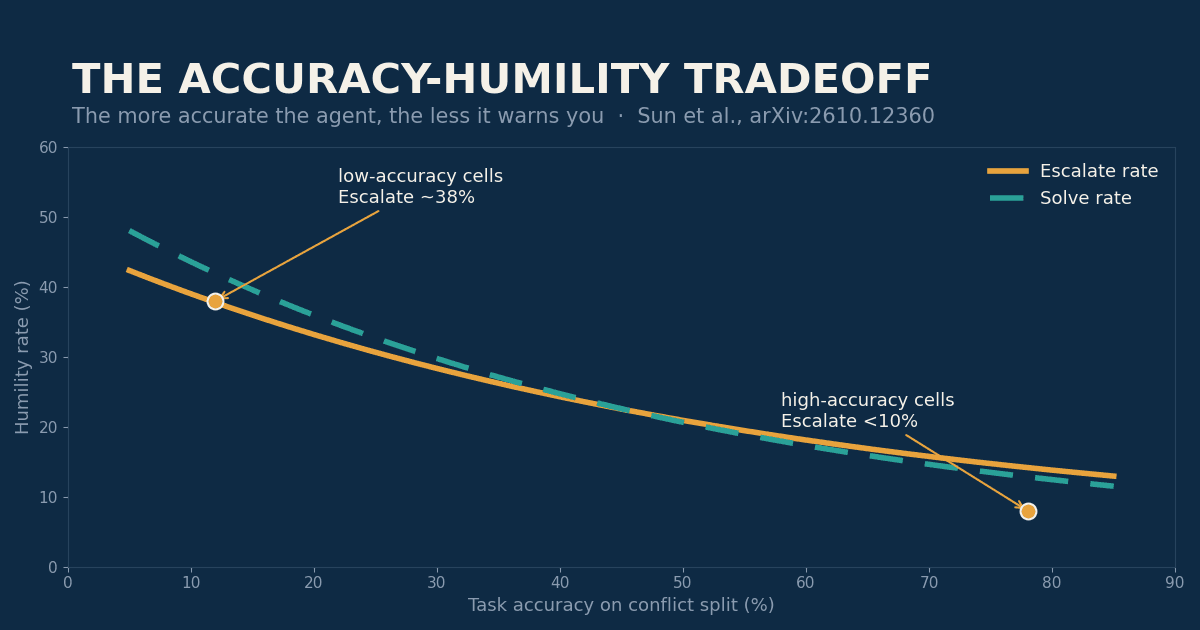
Your Agent Sees the Contradiction, Then Answers Confidently Anyway
Four agent systems scored on whether they flag uncertainty when evidence contradicts their memory. Accuracy and humility run in opposite directions, and a one-line prompt buys humility at the cost of accuracy.
Ibrahim Denis Fofanah·Oct 23, 2026·11 min
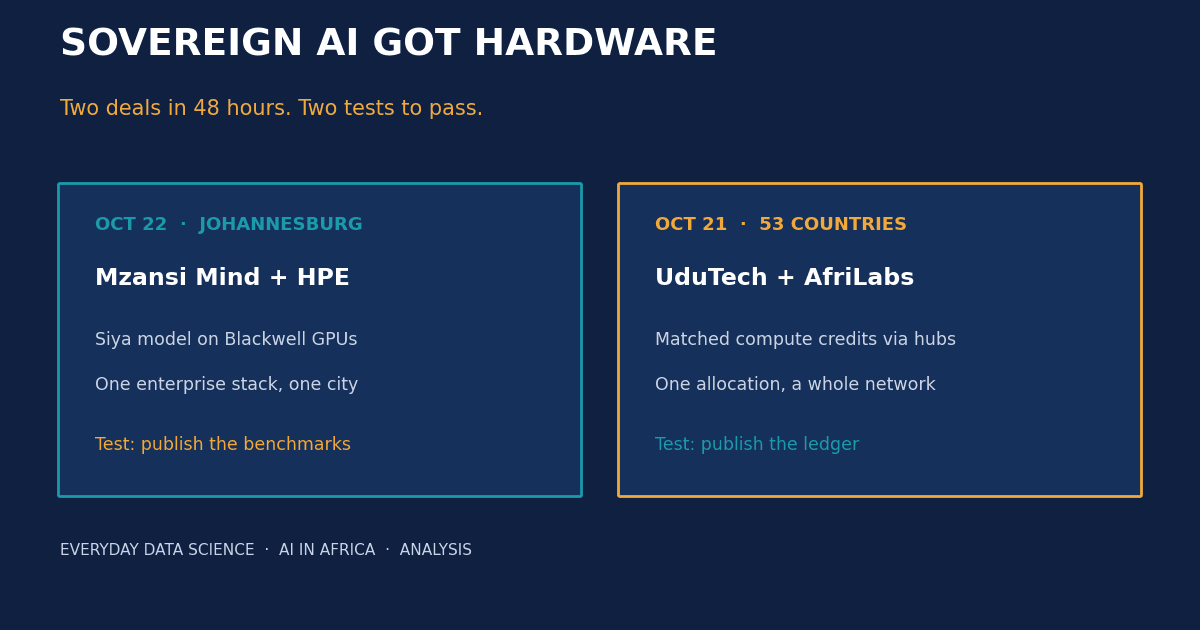
Sovereign AI Got Hardware This Week: Two Deals, Two Very Different Tests
Two announcements in two days put real hardware and real compute credits behind the word sovereign. One is a single enterprise stack in Johannesburg. The other is an allocation network across 53 countries. Neither published the numbers that would prove it works.
Ibrahim Denis Fofanah·Oct 22, 2026·10 min
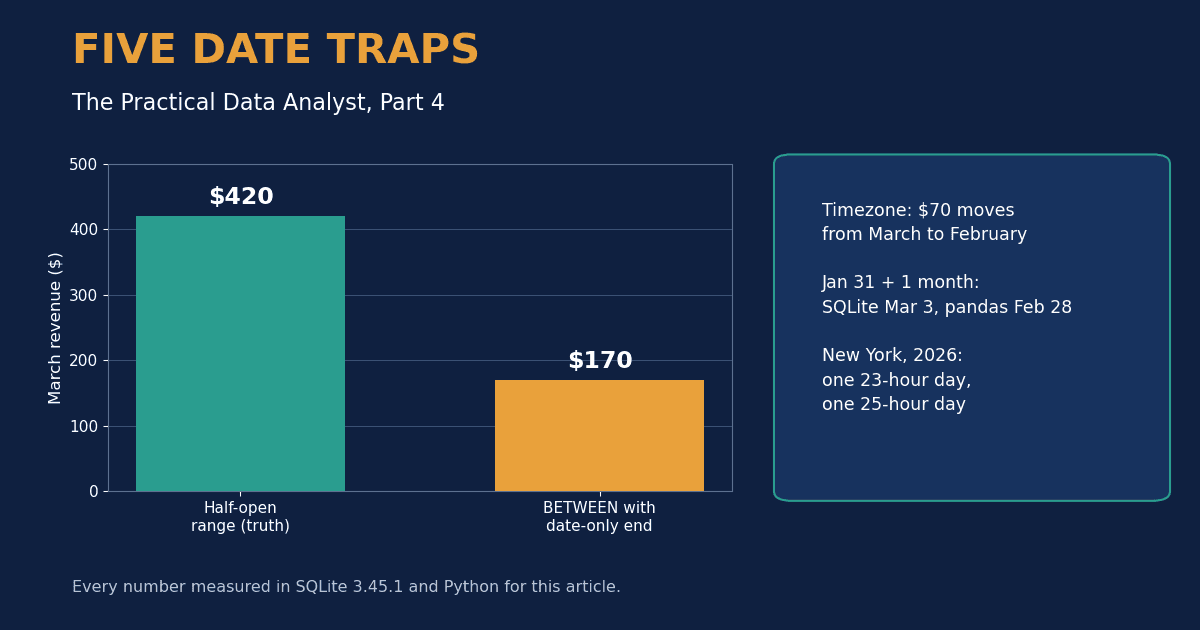
Five Date Traps That Move Money Between Months: I Measured Each One
Five controlled date experiments on a tiny orders table: a BETWEEN filter cut March from $420 to $170, a timezone moved $70 into February, and SQLite and pandas disagreed by three days on one month of arithmetic.
Ibrahim Denis Fofanah·Oct 21, 2026·10 min
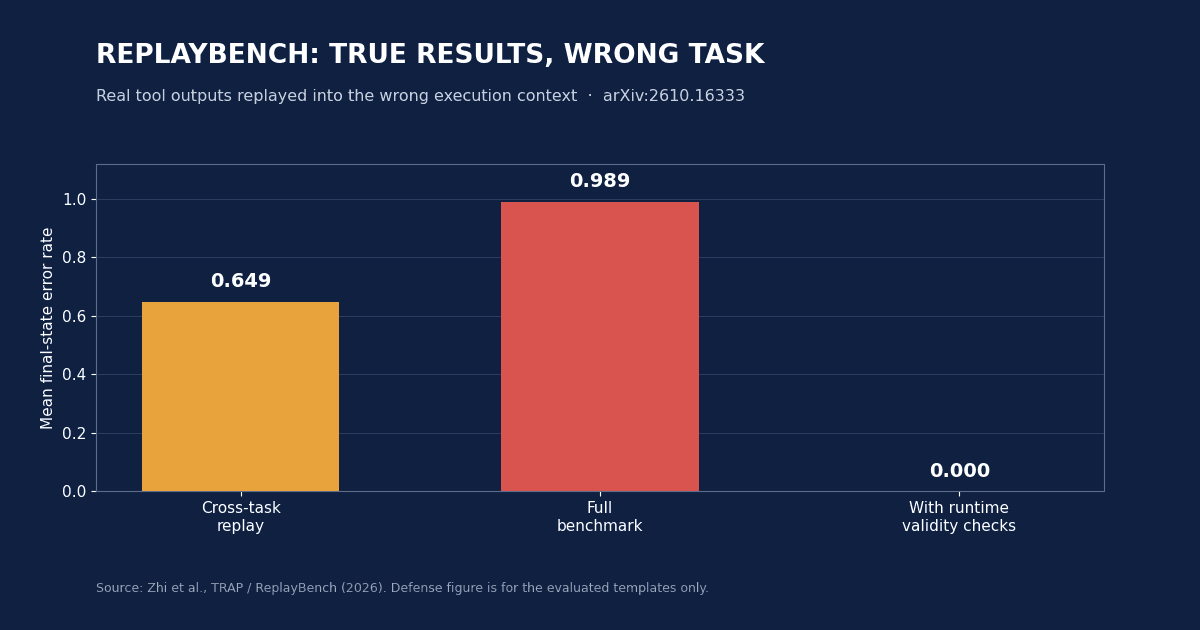
A True Tool Result Can Still Be Wrong: ReplayBench Found a 64.9% Error Rate
TRAP replayed real, unmodified tool results into the wrong task. Agents acted on them anyway: mean final-state error 0.649, and 0.989 across the full benchmark.
Ibrahim Denis Fofanah·Oct 20, 2026·11 min
Want an author page like this?
We publish practitioners. Pitch an idea or republish a post from your own blog.