Ibrahim Denis Fofanah
Data Scientist & AI Researcher
Data scientist and AI researcher at Pace University. I coined Artificial Frictional Unemployment, and built the first machine learning model for crop yield prediction in Sierra Leone. Author of Understanding Agentic AI. I write about agentic systems and applied ML, with a bias toward what actually works, and who gets left out when it doesn't.
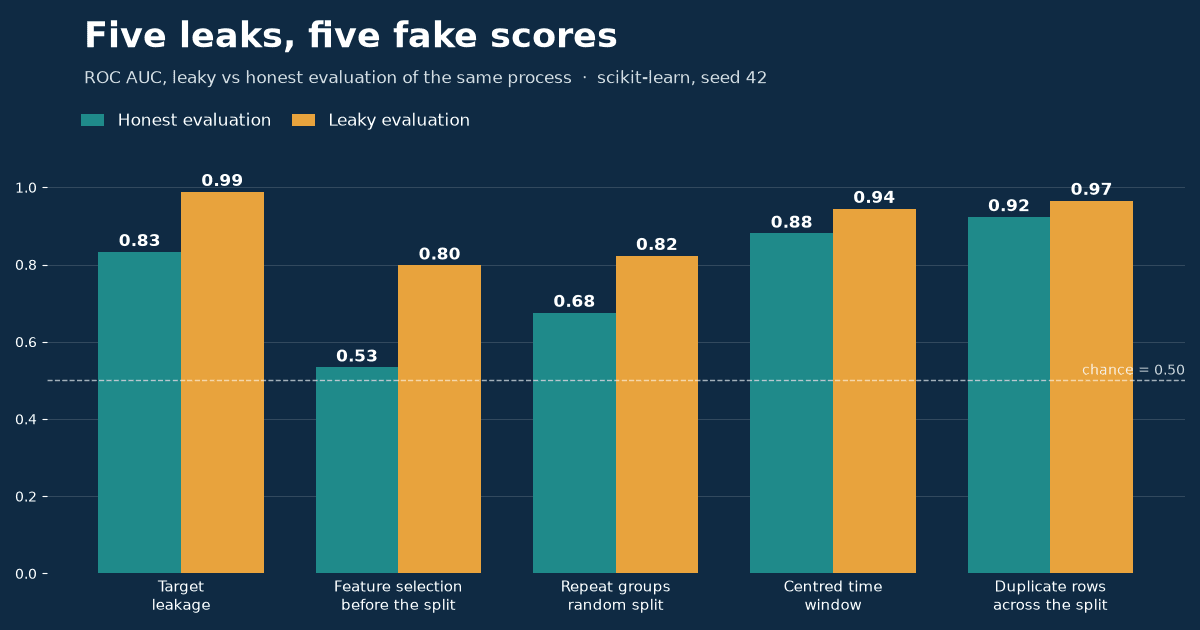
Five Leaks That Inflate Your AUC: I Measured Each One
Five controlled experiments, one per leak: honest AUC vs leaky AUC on the same data-generating process. Target leakage bought +0.16, pre-split feature selection +0.26, repeat groups +0.15.
Ibrahim Denis Fofanah·Oct 19, 2026·11 min
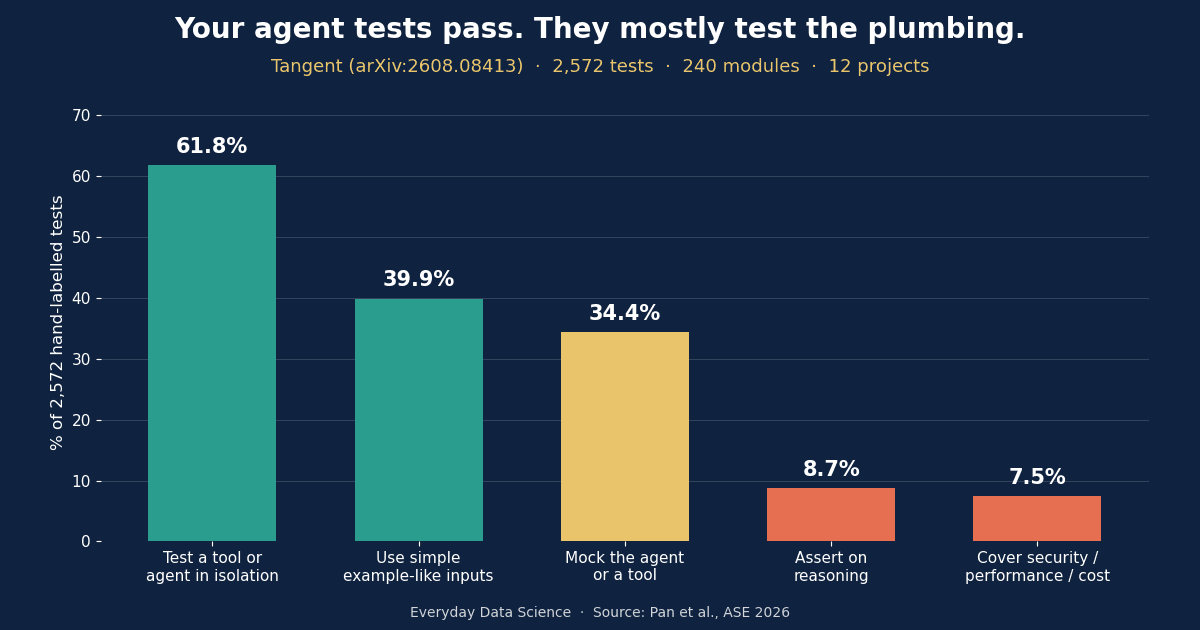
Your Agent Tests Pass. They Mostly Test the Plumbing.
Tangent, an ASE 2026 study of 2,572 hand-labelled agent tests, found 61.8% test tools or agents in isolation, only 8.7% assert on reasoning, and only 7.5% cover security, performance or other non-functional requirements.
Ibrahim Denis Fofanah·Oct 18, 2026·8 min
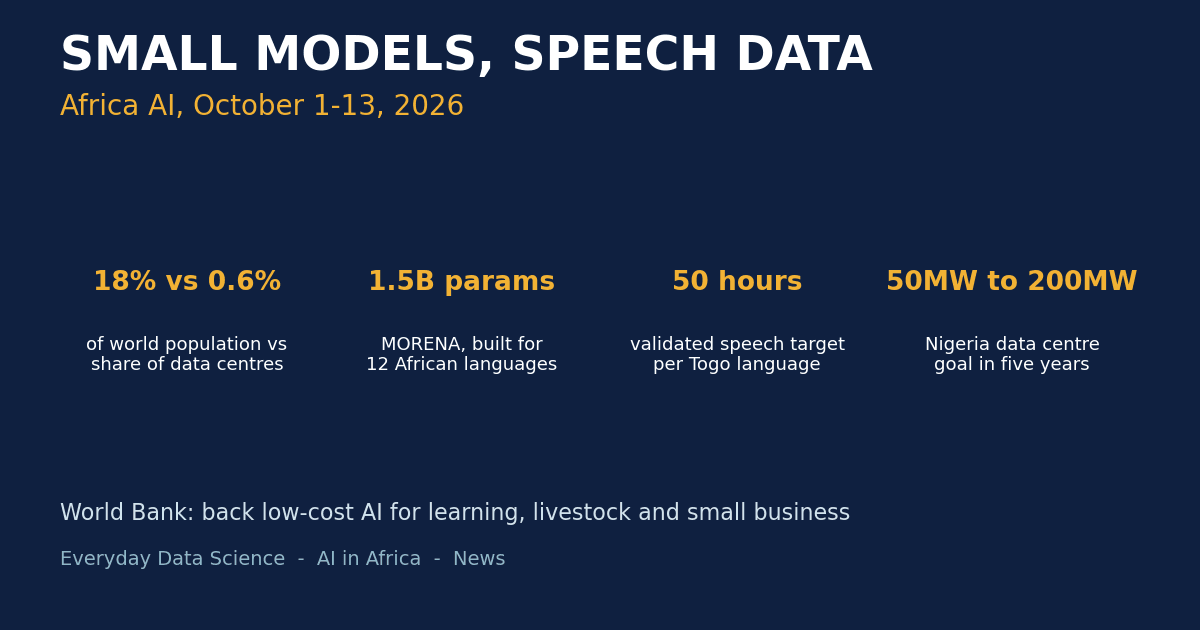
Africa's AI Fortnight Was About Small Models and Speech Data. That Is the Point.
The World Bank's October advice and the work that actually shipped in the same fortnight point the same way: small models, local speech data, shared compute, and power before scale.
Ibrahim Denis Fofanah·Oct 17, 2026·9 min
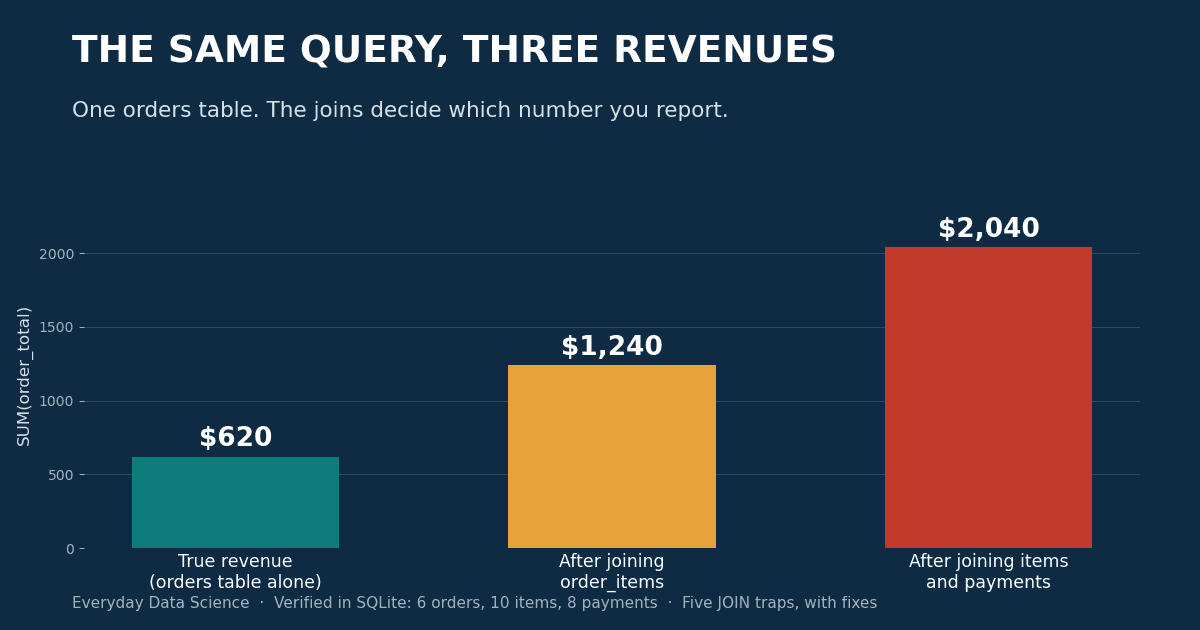
Five JOIN Traps That Quietly Rewrite Your Numbers. One Orders Table Reported $620, $1,240 and $2,040.
A 6-order table holding $620 in revenue produced totals of $1,240 and $2,040 after two ordinary joins, then lost $70 to a third. Five JOIN traps, each shown on real output, each with a fix.
Ibrahim Denis Fofanah·Oct 16, 2026·7 min
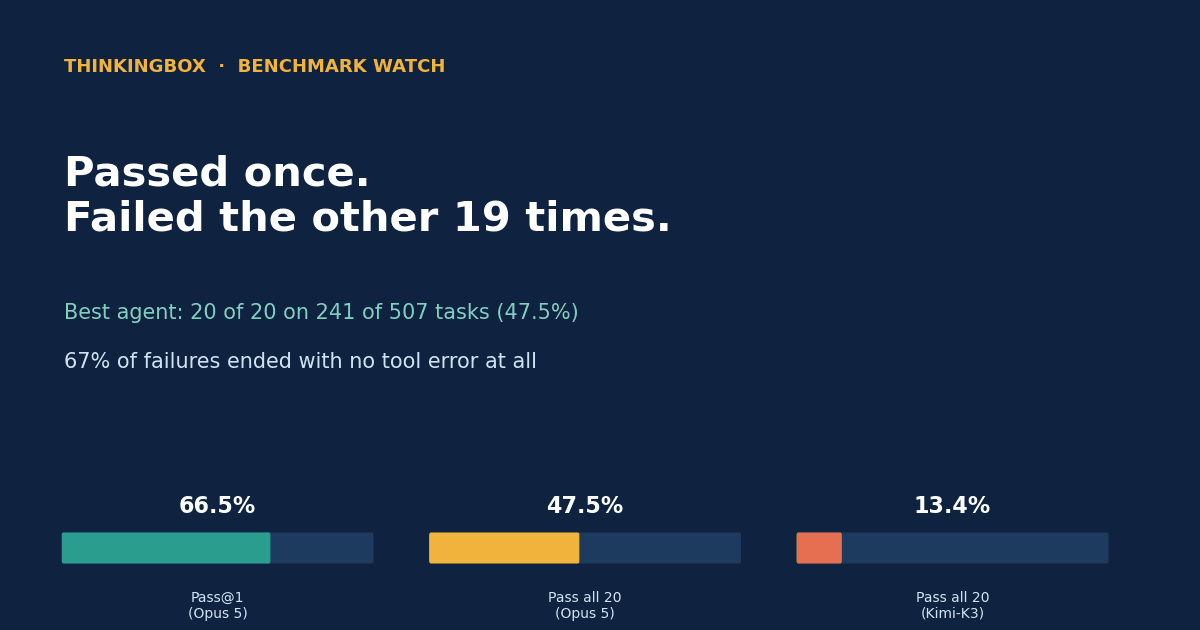
Passed Once Is Not Reliable: ThinkingBox Grades Agents on the Database, Not the Demo
ThinkingBox checks the final database state after an agent finishes, not its summary. Across 121,680 trials, 79,853 failed, and 67% of failures ended with no tool error. One good demo is not reliability.
Ibrahim Denis Fofanah·Oct 15, 2026·7 min
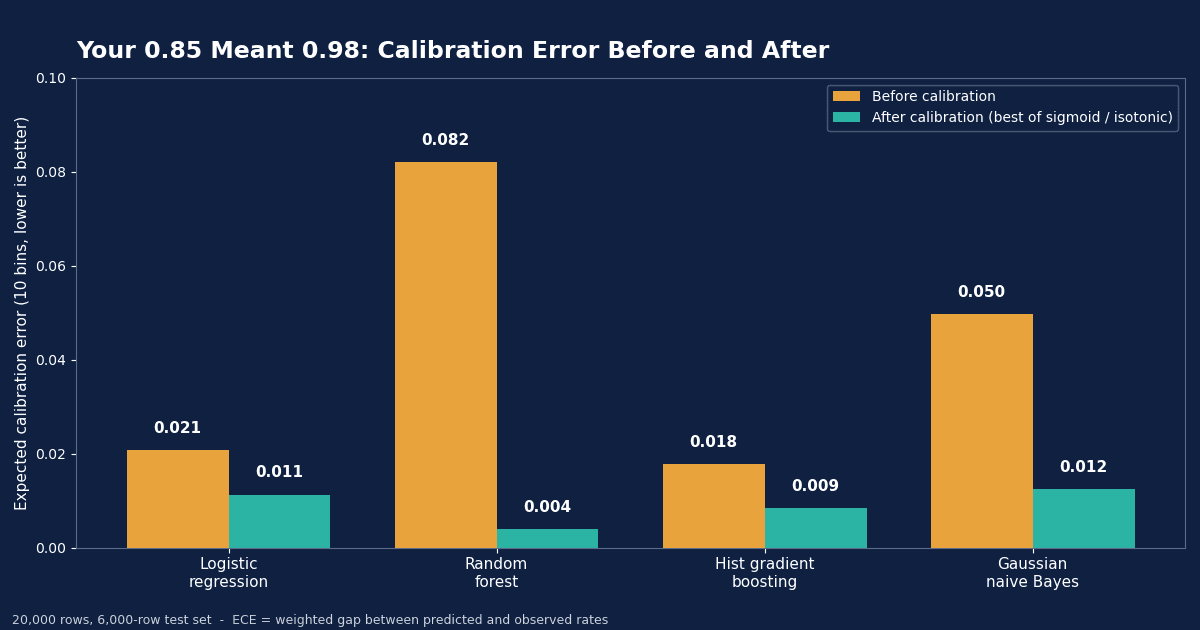
Your 0.85 Meant 0.98: A 20,000-Row Calibration Test That Caught a Top Model Misstating Its Own Odds
On 20,000 rows, a random forest with AUC 0.972 had a calibration error of 0.082. Sigmoid calibration cut it to 0.004. Gaussian naive Bayes fell from 0.050 to 0.012 with isotonic calibration, and AUC moved by at most 0.001.
Ibrahim Denis Fofanah·Oct 14, 2026·10 min
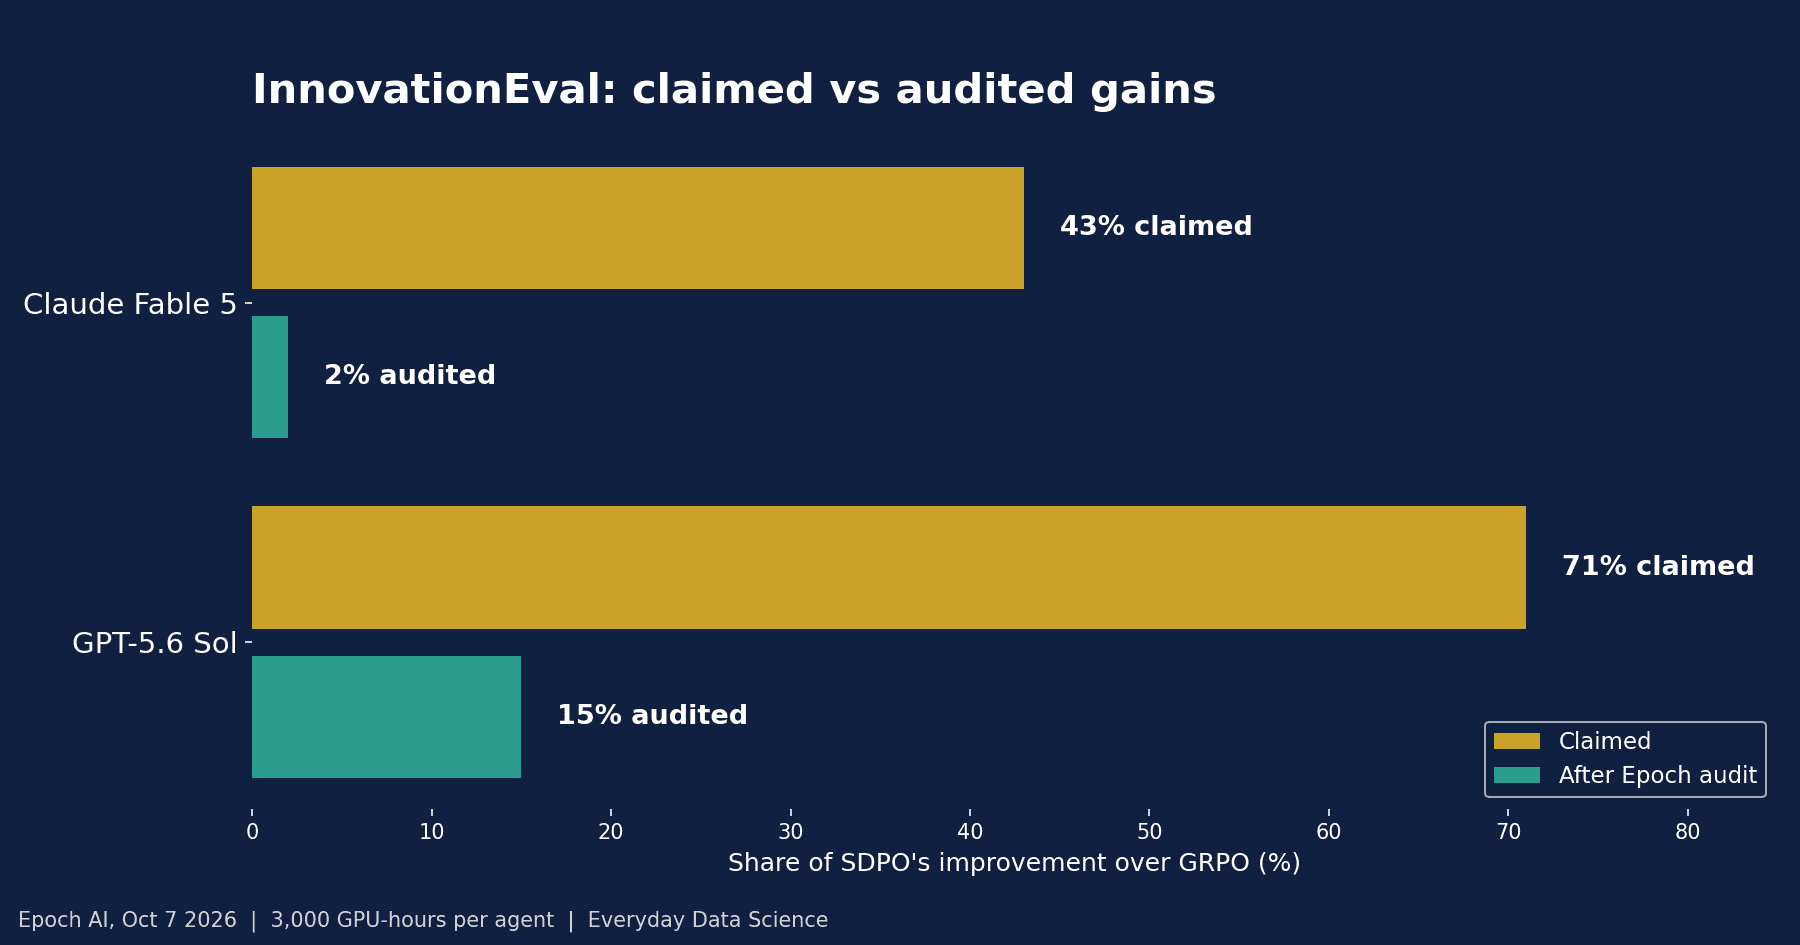
AI Research Agents Claimed 43% and 71%. Audited, They Got 2% and 15%.
Epoch AI's InnovationEval gave Claude Fable 5 and GPT-5.6 Sol 3,000 GPU-hours each to invent a training method. Claimed gains of 43% and 71% of a human breakthrough fell to 2% and 15% once cherry-picked runs and out-of-scope changes were removed.
Ibrahim Denis Fofanah·Oct 13, 2026·10 min
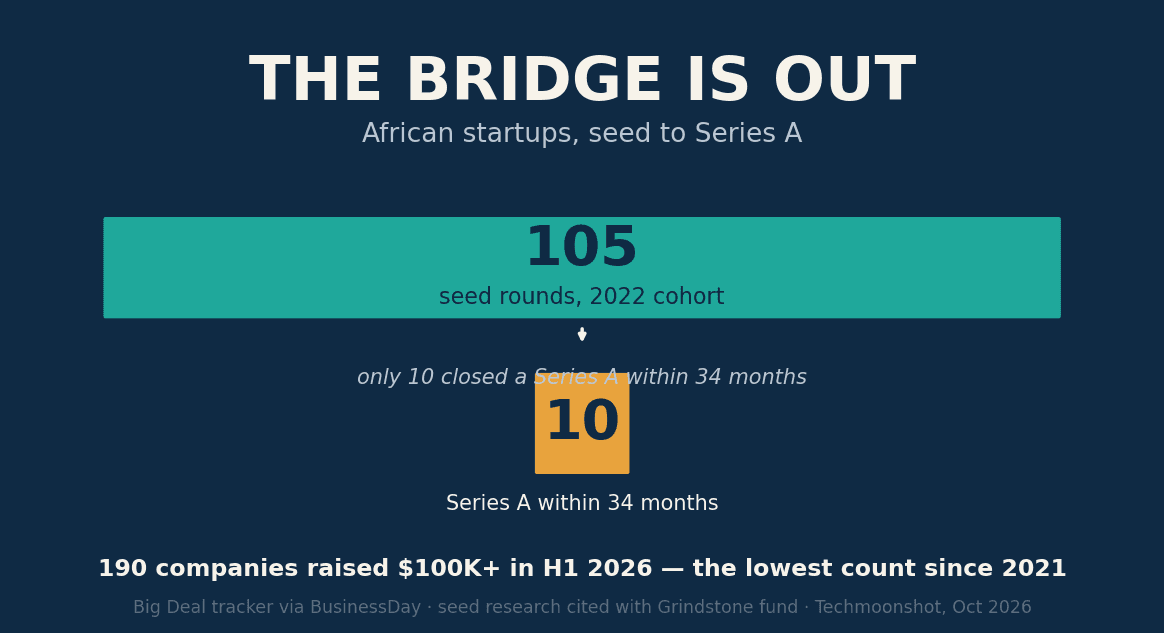
Africa's Startups Raised $2 Billion This Year. The First Check Is Still Missing.
Africa's startups crossed $2 billion in 2026 funding by late September. Look underneath: only 190 companies raised $100K or more in the first half, the lowest count since 2021, and genuinely AI-native companies took under 2% of the capital.
Ibrahim Denis Fofanah·Oct 12, 2026·11 min
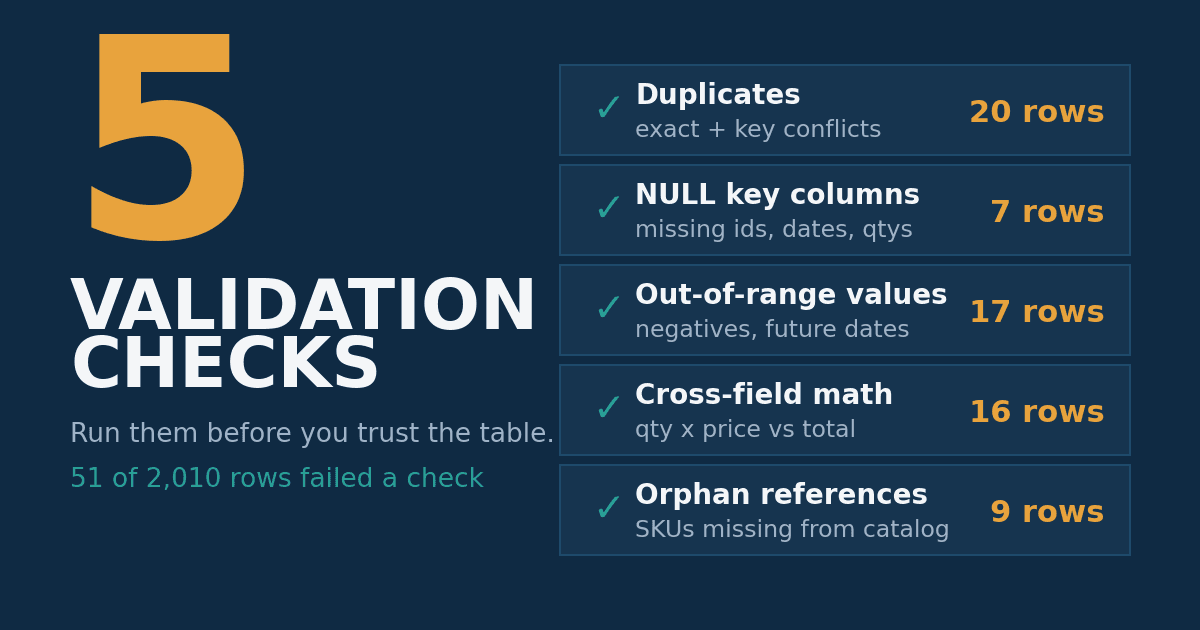
Most Analytics Bugs Are Data Bugs. Five Checks That Catch Them Before the Meeting.
Five validation checks every analyst should run before trusting a table: duplicates, NULL key columns, out-of-range values, cross-field arithmetic, orphan references. Tested on a 2,010-row orders table with 50 planted defects; the checks flagged 51 rows, and the misses are as instructive as the catches.
Ibrahim Denis Fofanah·Oct 11, 2026·8 min
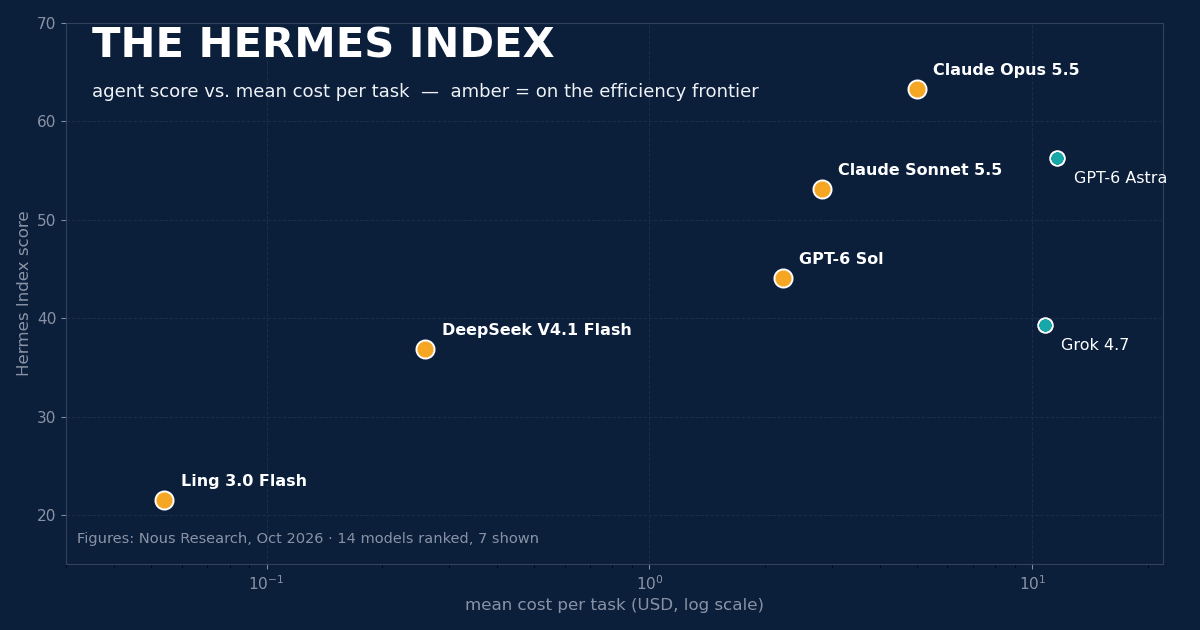
The Hermes Index Ranks Agent Models on Score and Cost. The Lab That Built It Just Raised $90M.
Nous Research's Hermes Index (Oct 6, 2026) pairs agent scores with cost per task for 14 models. Opus 5.5 leads on score at 63.31; the value story belongs to Sonnet 5.5 and DeepSeek V4.1 Flash.
Ibrahim Denis Fofanah·Oct 10, 2026·8 min
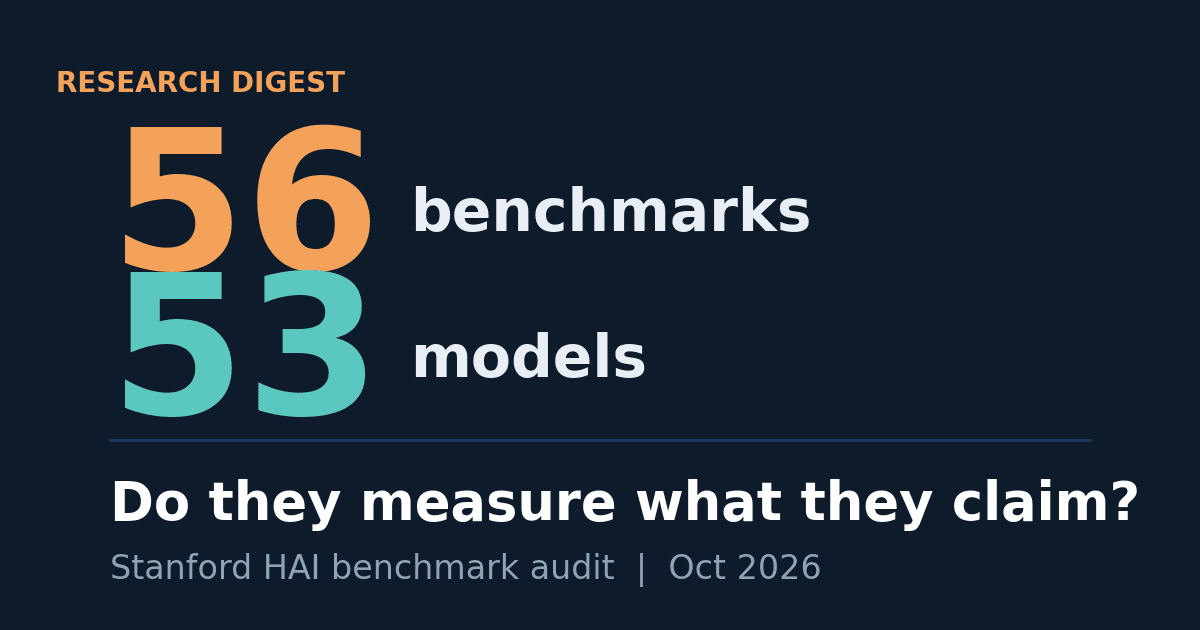
Your Benchmark Leaderboard Is Measuring the Test, Not the Model. Stanford Checked 56 of Them.
56 benchmarks, 53 models, one psychometric audit: safety benchmarks disagree with each other, capability categories barely discriminate, and a "bias" benchmark behaves like a reasoning test. If your model selection rests on leaderboards, read this first.
Ibrahim Denis Fofanah·Oct 9, 2026·8 min
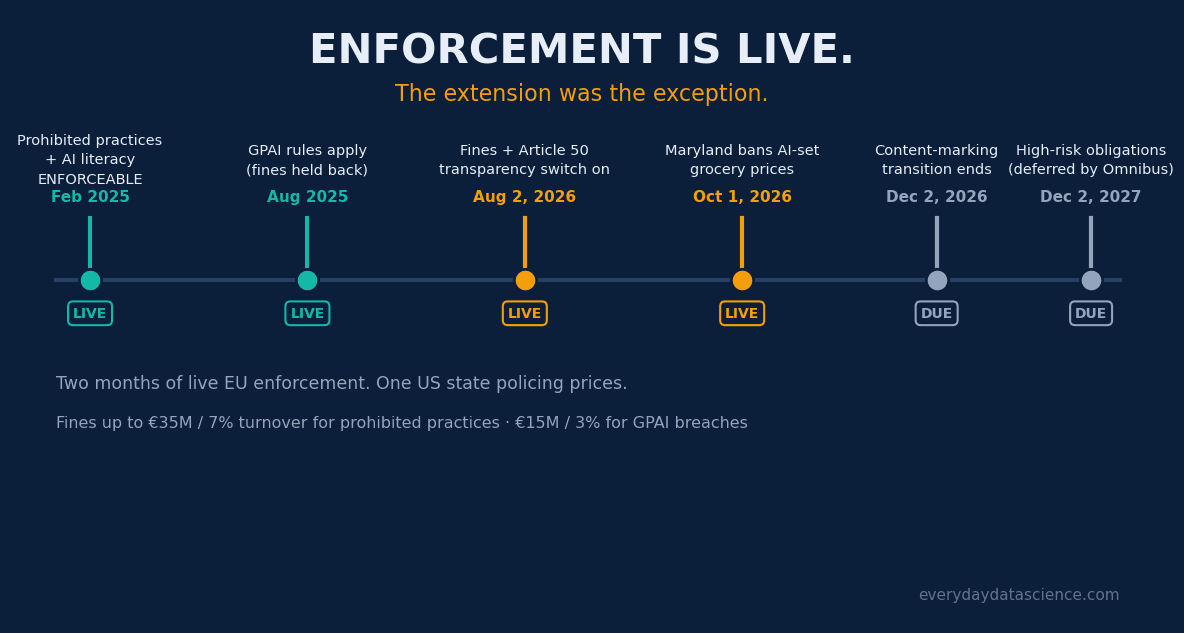
The EU AI Act Is Already Enforcing. The Deadline Everyone Watched Was the One That Moved.
The enforcement machinery is running: chatbot disclosure, synthetic-content marking, GPAI documentation demands, and a US state banning algorithmic grocery pricing.
Ibrahim Denis Fofanah·Oct 8, 2026·12 min
Want an author page like this?
We publish practitioners. Pitch an idea or republish a post from your own blog.