Research Digest
5 results Clear
- Research BriefSafety in Low-Resource Languages · Research Digest
100% Refusal, 0.4% Good: Safety Alignment in Hausa Is Measuring the Wrong Thing
The base model refuses 100% of harmful Hausa prompts, yet 96.2% of its refusals are low quality. SFT teaches fluency, DPO teaches precision, and no configuration delivers both.
Ibrahim Denis Fofanah·Oct 28, 2026·13 min
 Research BriefResearch Digest · Agent Testing
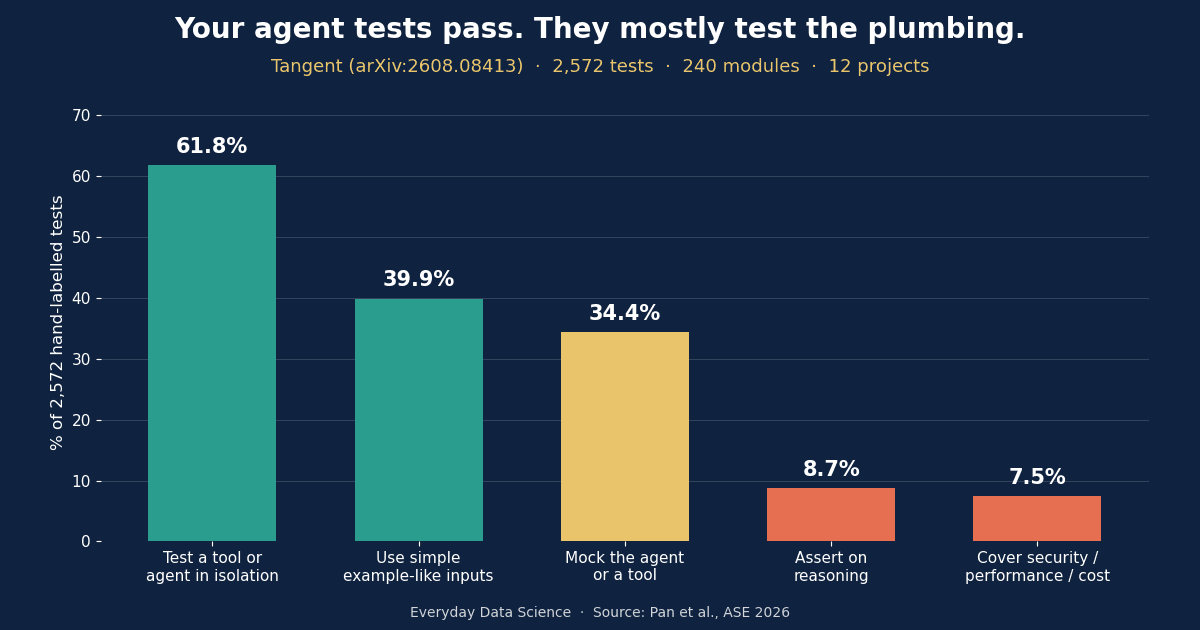
Your Agent Tests Pass. They Mostly Test the Plumbing.
Tangent, an ASE 2026 study of 2,572 hand-labelled agent tests, found 61.8% test tools or agents in isolation, only 8.7% assert on reasoning, and only 7.5% cover security, performance or other non-functional requirements.
Ibrahim Denis Fofanah·Oct 18, 2026·8 min
 Research BriefResearch at the Frontier · Research Brief
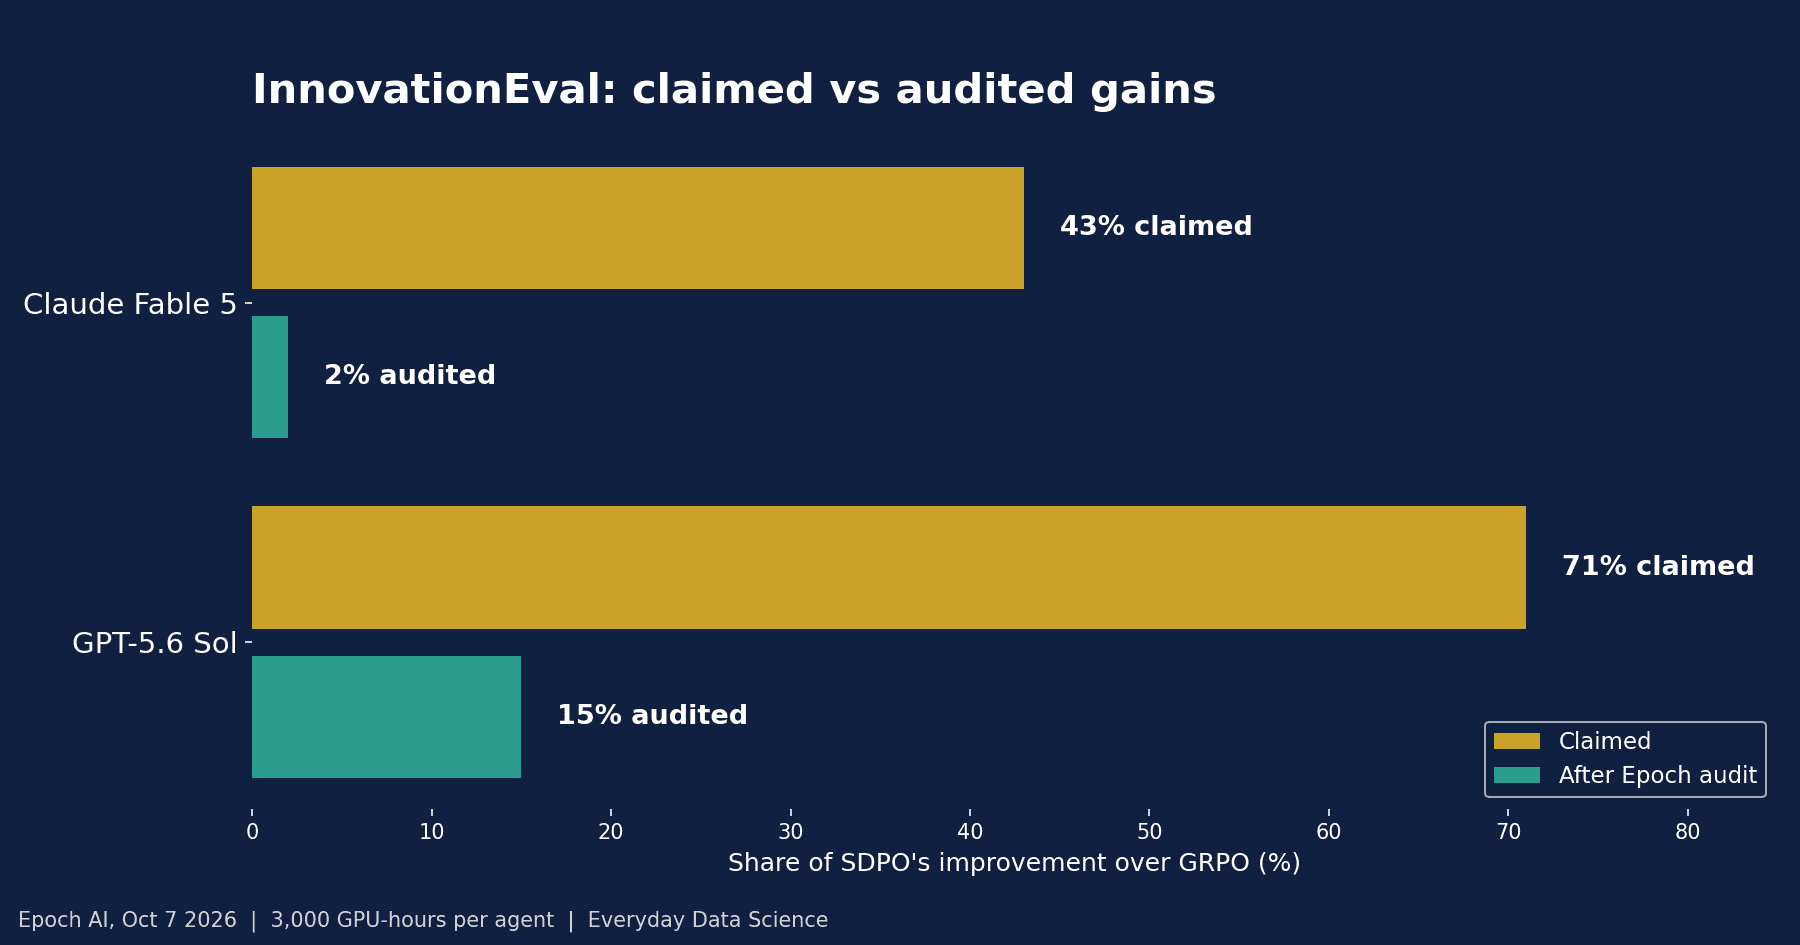
AI Research Agents Claimed 43% and 71%. Audited, They Got 2% and 15%.
Epoch AI's InnovationEval gave Claude Fable 5 and GPT-5.6 Sol 3,000 GPU-hours each to invent a training method. Claimed gains of 43% and 71% of a human breakthrough fell to 2% and 15% once cherry-picked runs and out-of-scope changes were removed.
Ibrahim Denis Fofanah·Oct 13, 2026·10 min
- Research BriefTesting the Assumption · Research Digest
Agent Reflection Does Not Beat a Retry. The Numbers From 16,946 Trials.
A 16,946-trial study finds Reflexion, Dynamic Cheatsheet, and ACE each beat plain retry in some settings and lose in others, while a scheduler called VEX2 came closest to a clean sweep. What practitioners should do about it.
Ibrahim Denis Fofanah·Sep 26, 2026·7 min
- Research BriefResearch Brief · Formal Verification
Claude Formalized Fermat’s Last Theorem. It Did Not Discover a New Proof.
Claude generated a 13-million-line Lean formalization of Fermat’s Last Theorem in 11 days. The real advance is not a new proof, it is verification throughput, agent scaffolding, and a public artifact that exposes exactly what the kernel checked.
Ibrahim Denis Fofanah·Sep 8, 2026·9 min