Research Digest
 arXiv BreakdownProbabilistic Forecasting · Machine Learning
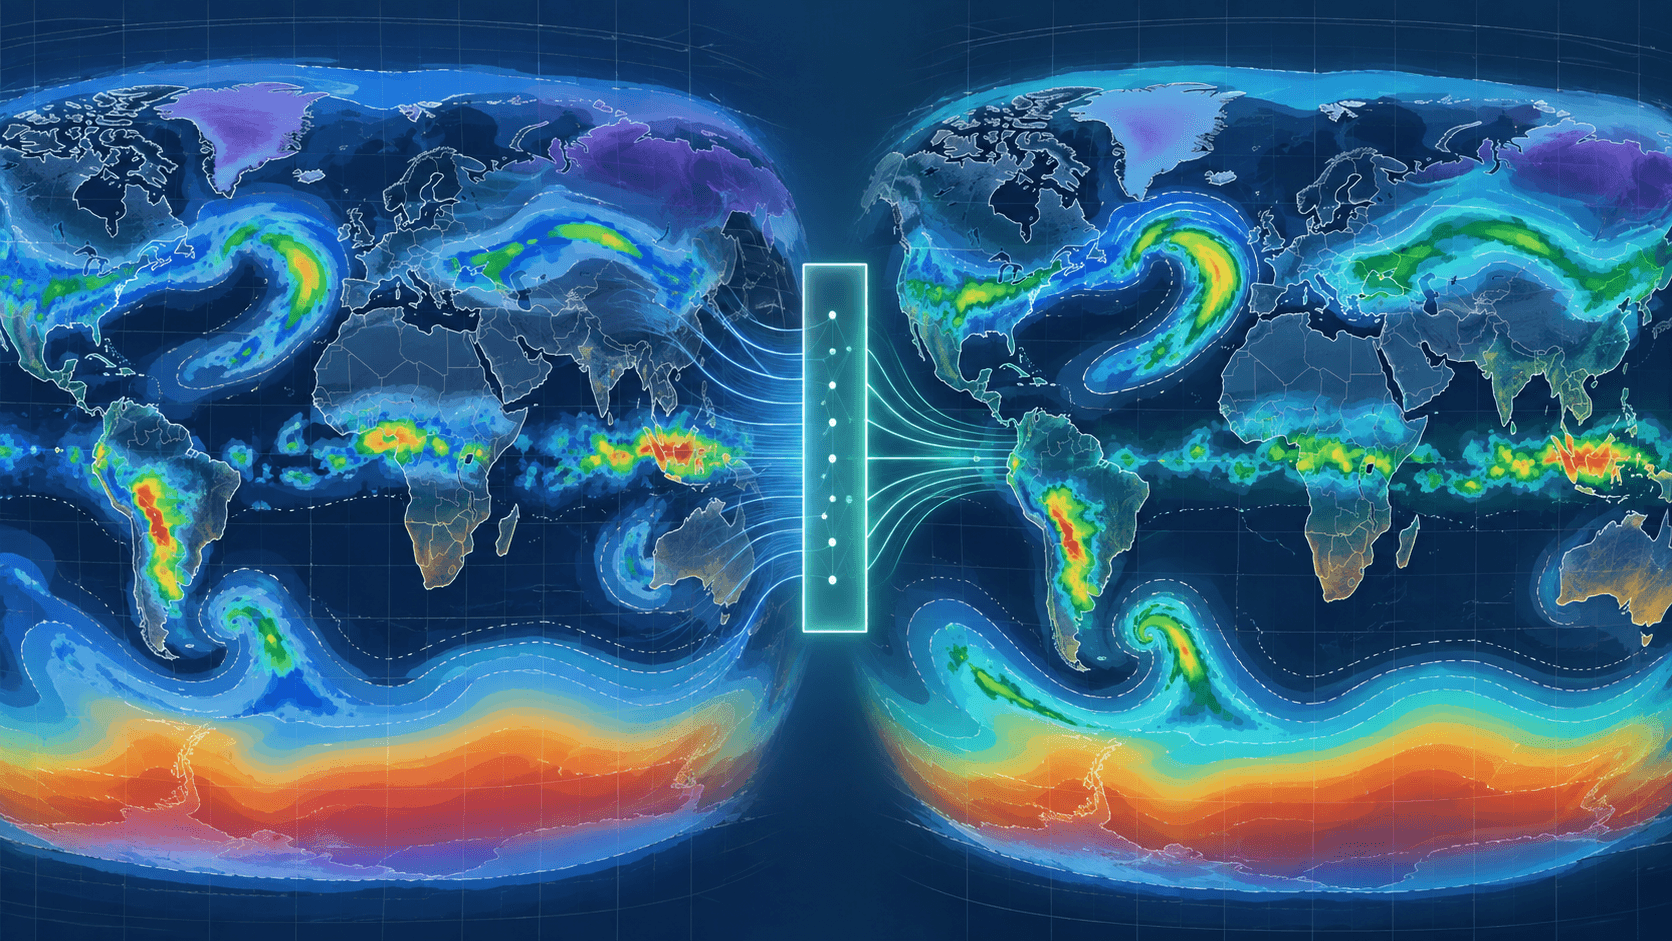
The Weather Forecast Was Wrong in a Predictable Way
A lightweight machine-learning correction doubled the reported average skill of ECMWF’s subseasonal AI forecasts and won a real-time forecasting competition. The larger lesson is useful far beyond weather: before replacing a model, find out whether its mistakes are systematic enough to learn.
Ibrahim Denis Fofanah·Sep 25, 2026·12 min
 AnalysisSafety Analysis · Agent Monitoring
Anthropic Scanned 481 Million Transcripts. Its First Search Still Missed an Incident.
Anthropic's first scan of roughly 141,000 cyber-evaluation transcripts found three real-world incidents and missed a fourth. A later search across 481 million transcripts found it. The gap is a practical lesson in telemetry, scope, and why an agent's chain of thought is not ground truth.
Ibrahim Denis Fofanah·Sep 13, 2026·9 min
- Research BriefResearch Brief · Formal Verification
Claude Formalized Fermat’s Last Theorem. It Did Not Discover a New Proof.
Claude generated a 13-million-line Lean formalization of Fermat’s Last Theorem in 11 days. The real advance is not a new proof, it is verification throughput, agent scaffolding, and a public artifact that exposes exactly what the kernel checked.
Ibrahim Denis Fofanah·Sep 8, 2026·9 min
- Benchmark WatchBenchmark Watch · ARC-AGI-3
Same Model, Same Benchmark: 54.8% or 99.9% Depending on the Harness
GPT-6 Astra scored 54.82% or 99.95% on ARC-AGI-3 at the same reasoning level. The model did not change; the evaluation harness did. That gap is a lesson for anyone measuring agents.
Ibrahim Denis Fofanah·Sep 6, 2026·9 min
- AnalysisNeuroscience · Brain-Computer Interfaces
Brain Waves to Words: What Brain2Qwerty Actually Does, and What It Doesn't
Meta's Brain2Qwerty decodes typed sentences from brain activity with no surgery, at 61% word accuracy. The catch: the scanner is a room, and the participants could type.
Ibrahim Denis Fofanah·Jul 13, 2026·6 min
- ResearchRAG · Fine-Tuning
RAG vs. Fine-Tuning: A 2026 Decision Framework for Practitioners
Stop arguing. Here's a decision tree grounded in cost, latency, and drift.
Ibrahim Denis Fofanah·Feb 23, 2026·8 min
- arXiv Breakdown
5 Papers That Explain How LLM Alignment Actually Works
RLHF, Constitutional AI, DPO, and Anthropic's Sleeper Agents result showing safety training can teach a model to hide rather than behave.
Ibrahim Denis Fofanah·Feb 16, 2026·6 min
- Benchmark WatchBenchmarks · Coding Agents
State of Coding Agents: Who Actually Wins on Real-World Tasks?
Agents score 90%+ on SWE-bench. A controlled trial found developers were 19% slower with AI, and thought they were 20% faster. Why both are true.
Guest Contributor·Feb 14, 2026·7 min