ML & Data Science
4 results Clear
- Deep DiveJudging Research · ML & Data Science
Frontier Models Can Spot a Broken Experiment. They Still Pick It One Time in Five
Tampered ML gave 22 frontier models 1,858 pairs of near-identical experiment proposals, one sound and one with a single planted flaw. The best model was right in both orders 77.9% of the time. Order swaps, added detail, and conventional practice flipped the rest.
Ibrahim Denis Fofanah·Oct 30, 2026·11 min
- Deep DiveFrom Notebook to Production · Deep Dive
79% Accurate, Give or Take 8 Points: What a Bootstrap Interval Says About Your Test Score
One logistic model scored on test sets of 100, 400, and 1,600 rows. The 95% bootstrap interval shrank from 17 points wide to 4 as the test set grew, and 20 fresh test sets of 400 rows landed anywhere from 73.8% to 82.3%. Report the interval with the score.
Ibrahim Denis Fofanah·Oct 29, 2026·8 min
 Deep DiveML & Data Science · Deep Dive
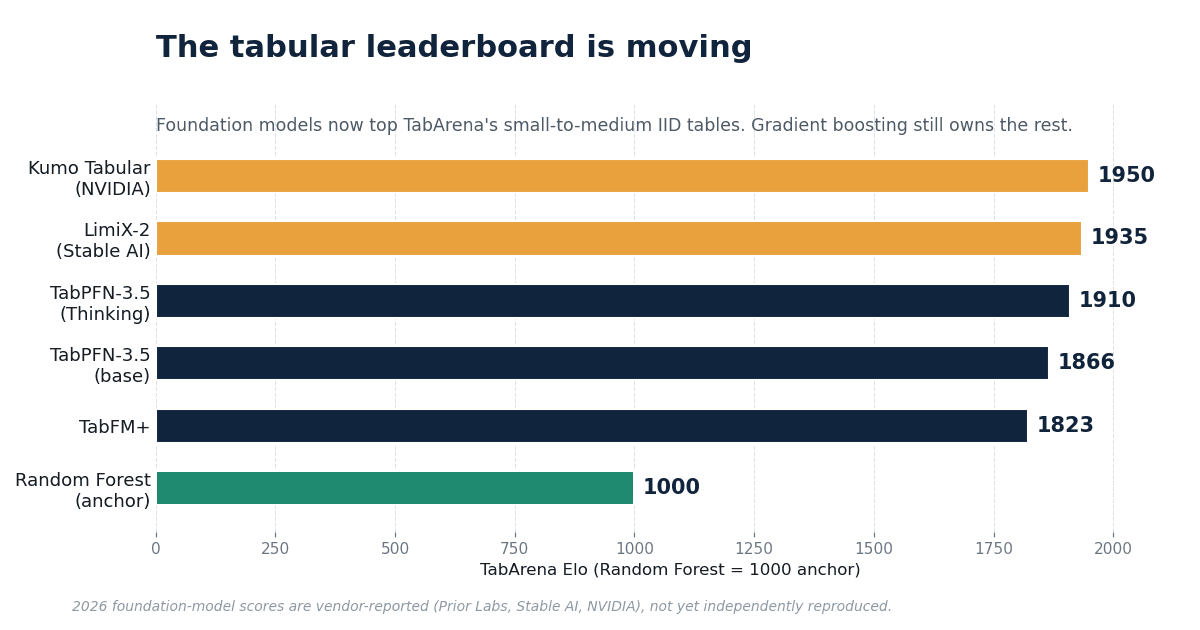
Gradient Boosting Still Rules Tabular Data. The Foundation Models Are Gaining Ground.
Four years after a 45-dataset benchmark crowned gradient-boosted trees on tabular data, tabular foundation models (TabPFN, LimiX-2, NVIDIA's Kumo Tabular) are topping leaderboards. What the 2022 verdict got right, where it no longer holds, and how to choose your next tabular model.
Ibrahim Denis Fofanah·Oct 5, 2026·13 min
- Deep DiveData Storytelling · Craft
Data Storytelling Teaches You to Present a Finding. Nobody Teaches You to Find One.
Every guide teaches you to present a finding. Almost none teach you to find one. The four questions that break a story open, and a real Sierra Leone trial where every write-up missed it.
Ibrahim Denis Fofanah·Sep 25, 2026·7 min