ML & Data Science
8 results Clear
 ExplainerFrom Notebook to Production · Explainer
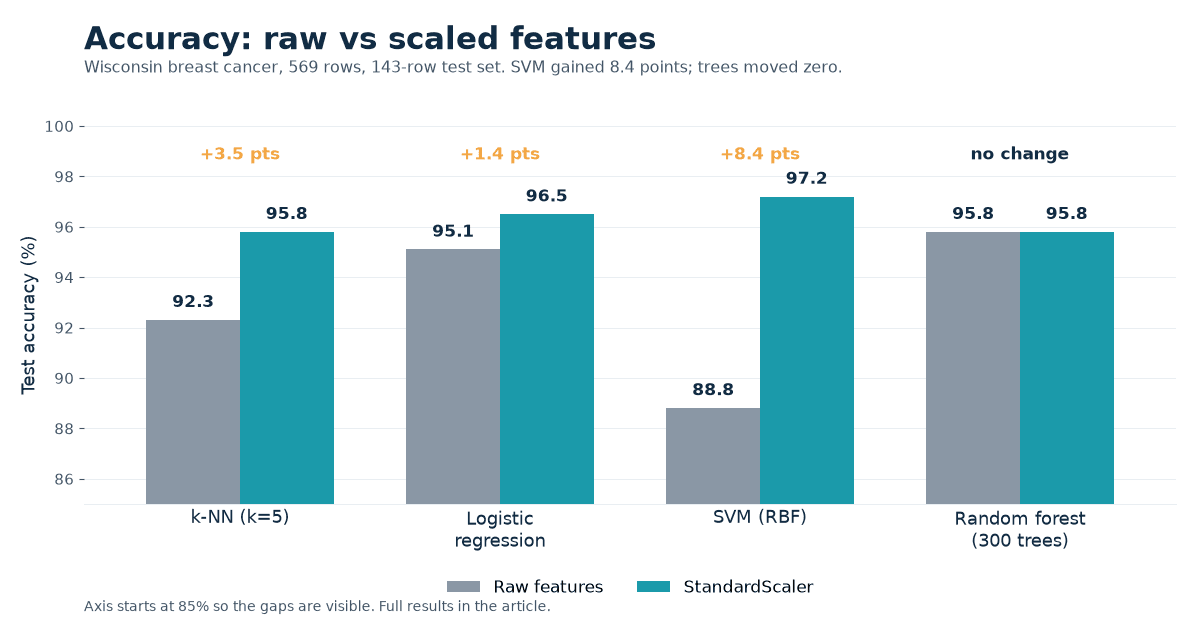
Scaling Gave SVM 8 Points and Trees Nothing. I Ran Four Models Raw and Scaled.
SVM went from 88.8% to 97.2% accuracy with one preprocessing line. Random forest moved zero. Logistic regression stopped warning and converged in 20 iterations instead of 1,000.
Ibrahim Denis Fofanah·Nov 7, 2026·10 min
 ExplainerFrom Notebook to Production · Explainer
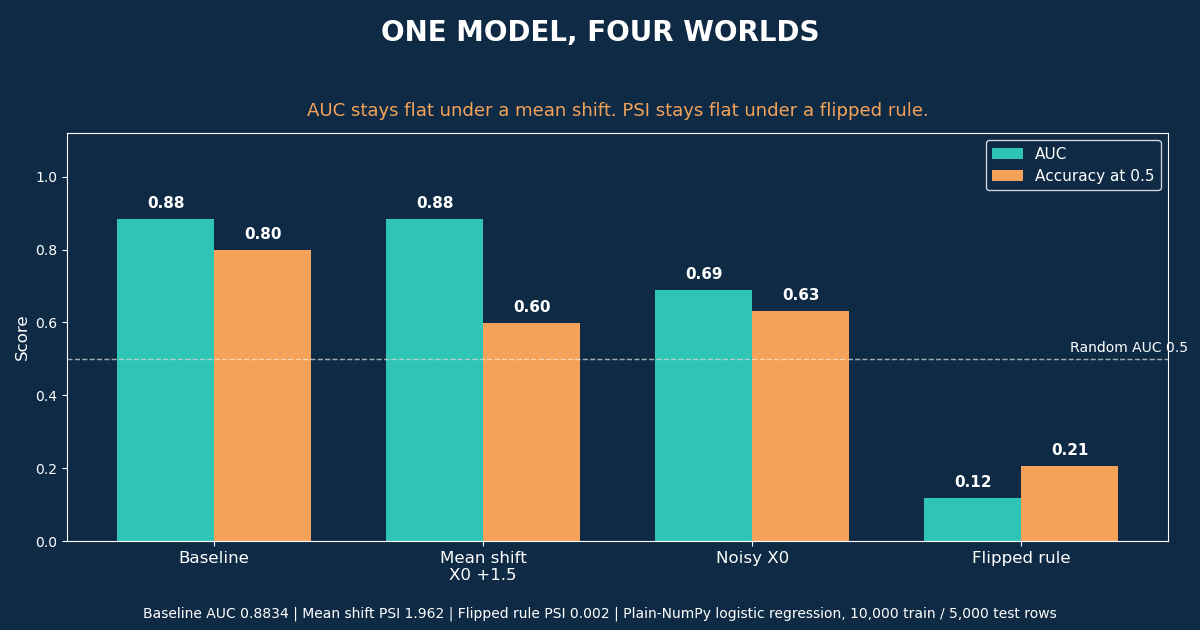
Drift Is Three Different Failures, and One Metric Cannot See Them All
One logistic model, four test scenarios: a mean shift that broke accuracy but not AUC, added noise that hurt both, and a flipped rule that PSI could not see at all. The table, the code, and the monitoring checklist.
Ibrahim Denis Fofanah·Oct 24, 2026·9 min
 ExplainerFrom Notebook to Production · Explainer
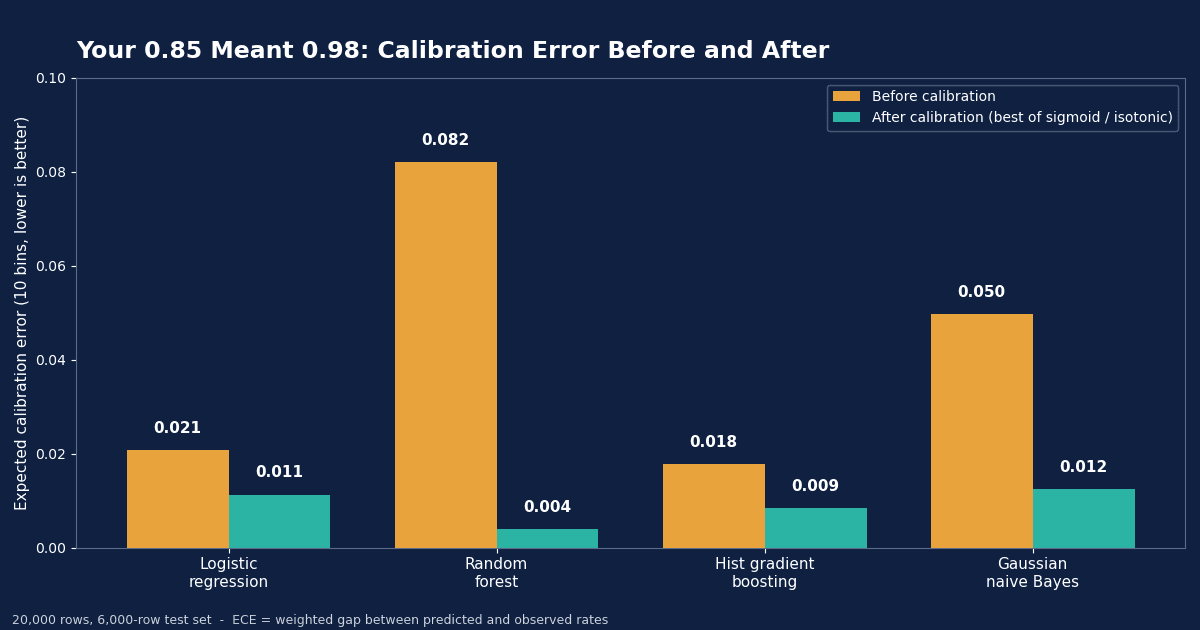
Your 0.85 Meant 0.98: A 20,000-Row Calibration Test That Caught a Top Model Misstating Its Own Odds
On 20,000 rows, a random forest with AUC 0.972 had a calibration error of 0.082. Sigmoid calibration cut it to 0.004. Gaussian naive Bayes fell from 0.050 to 0.012 with isotonic calibration, and AUC moved by at most 0.001.
Ibrahim Denis Fofanah·Oct 14, 2026·10 min
- ExplainerAI Foundations · Explained
What Are Embeddings? How Meaning Becomes Math
An embedding turns meaning into a location so that similarity becomes distance. That one idea is the engine under semantic search, recommendations, and the retrieval half of every RAG system, and it is cheap enough to run on your own data.
Ibrahim Denis Fofanah·Sep 25, 2026·7 min
- ExplainerFrom Notebook to Production · Part 1
Your Model Works in a Notebook. That Is the Easy Part.
A notebook proves a model can work once. Production requires it to work continuously, on unseen data, within a budget, and to fail safely. The five questions that define the gap, and why deployment is the scarce skill.
Ibrahim Denis Fofanah·Sep 25, 2026·7 min
- ExplainerML & Data Science · Under the Hood
Reasoning Models Explained: What Test-Time Compute Actually Costs You
Letting a model think longer is a real capability (DeepSeek-R1 lifted AIME accuracy from 15.6% to 71.0%) and a real bill you pay in tokens and latency on every query. When it is worth paying, and when it is not.
Ibrahim Denis Fofanah·Aug 11, 2026·7 min
- ExplainerFrom Notebook to Production · Part 2
Serving a Model: Endpoint, Batch, or Embedded?
Three ways to serve a model, endpoint, batch, or embedded, and the one question that decides which. Most people default to the always-on endpoint. It is the priciest and most fragile option, and usually the wrong one.
Ibrahim Denis Fofanah·Aug 8, 2026·7 min
 ExplainerData Thinking · Part 1
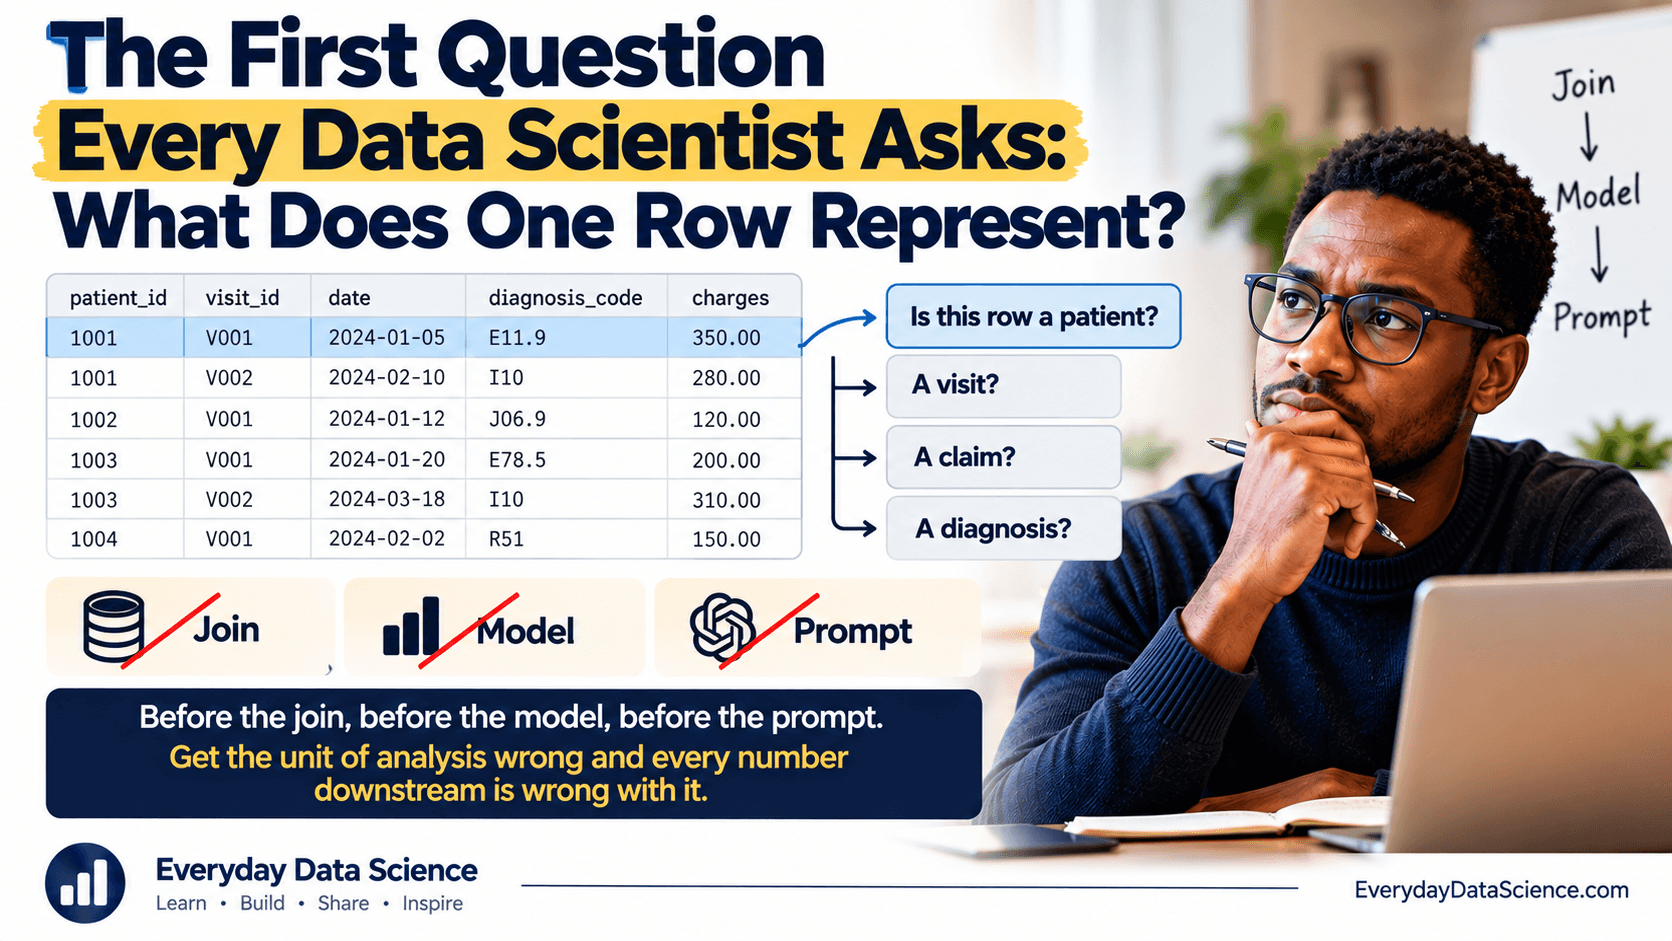
The First Question Every Data Scientist Asks: What Does One Row Represent?
A falling average order value triggered a discount review. The arithmetic was right and the table was wrong. Why the grain of a table decides whether every metric built on top of it is true.
Ibrahim Denis Fofanah·Jul 23, 2026·12 min